How to build an it disaster recovery plan that actually survives a cyber crisis in 2026
 Quincy Xanthos·October 22, 2026·17 min
Plan a resilient it disaster recovery plan for 2026. Learn risk analysis, RTO/RPO, data recovery, and testing to minimize downtime after cyber incidents.
A cyber threat can derail uptime in minutes, yet most DR plans still chase availability as if cyber risk were a minor outage. Blindly lifting RTO targets without cyber context often leaves critical assets waiting when attackers pivot. The practical takeaway is to start from asset criticality and known-attack patterns, not from uptime quotas alone.
This piece cuts through the common drift by tying recovery objectives to real-world cyber risk, not generic SLAs. In 2026, CISOs report that nearly half of recoveries fail when playbooks don’t account for encryption, data exfiltration, and supply-chain compromise. Expect clear guidance on scoping, validation, and iteration that stays actionable under real cyber pressure. Most failed DR efforts trace to siloed data and slow escalation, not the threat itself.

It disaster recovery plan in 2026: what changes for cyber resilience
In 2026, DR planning must treat cyber threats as the primary breakage vector, not an afterthought to uptime. Ransomware sophistication has grown alongside cloud-first environments and hybrid work patterns, so recovery sits at the intersection of data integrity, identity, and rapid failover across multi-cloud estates. A modern DR plan starts with cyber resilience as the default objective, not a separate appendix.
Why cyber-first recovery matters in 2026
The attack surface has shifted from on‑premise silos to shared services across clouds. I dug into guidance that emphasizes risk-based objectives, where RTO and RPO must reflect real cyber risk rather than generic availability targets. The aim is to minimize data exposure and speed restoration of critical workstreams while preserving regulatory posture. This shift means you treat data lineage, access controls, and recovery testing as core knobs you turn before incident response.
Three real-world pivots you should adopt
- Automated failover across clouds, Rather than a manual sequence, automated orchestration handles failover, validation, and restoration. This reduces recovery time and lowers the chance of human error during a crisis, especially when teams are dispersed. The trend is toward fast, verifiable switchover that keeps business services aligned with regulatory expectations.
- Integrated incident response, DR and IR teams share runbooks, playbooks, and run-tested play sequences. When a detection fires, the recovery workflow knows exactly which data sets to restore, which systems to bring online, and how to validate integrity before customers see any disruption.
- Cyber recovery objectives across the stack, Recovery targets now span data, apps, identities, and configurations. You should define what counts as recovered for each tier of system, not just whether a service is online. This ensures that restored environments aren’t re-exposed to the initial threat vector.
What a modern DR plan must cover beyond backups
A 2026 plan must map cyber resilience into every recovery activity. You need data‑centric controls that show what’s recoverable, when, and from where. Include threat modeling for cloud-native services, tailored restore playbooks for hybrid environments, and validation procedures that prove data integrity after restoration. Testing cycles should simulate real attack paths, not only outages, so your teams prove resilience under ransomware-style scenarios. You should also embed regulatory alignment, data retention, encryption at rest and in transit, and audit trails, into every recovery checkpoint.
Most cyber incidents hinge on a single weak recovery token or an untested restoration path, not the initial breach itself. This is why automated failover, integrated IR, and cyber‑aware targets must be non‑negotiable parts of your DR blueprint. In 2026, recovery is a cyber capability, not a backup chore.
From a governance perspective, expect more frequent updates to runbooks as cloud services evolve. I cross-referenced guidance that highlights risk-informed objectives and evidence-based testing as central to credible cyber resilience. The evolving landscape is summarized in current IT guidance that frames recovery as a bounded, testable cyber capability, not a quarterly checkbox. For a concise overview of the underlying practice, see guidance on IT recovery planning in modern frameworks. Disaster recovery planning guidance discusses aligning recovery actions with critical data and processes, which mirrors what you’ll implement in 2026. What is workflow automation in 2026 and why it matters for modern teams
If you want one concrete takeaway, it’s this: automate the recovery path with clear, cyber-aware objectives, then validate that path under attack-like conditions. Your stakeholders will thank you when downtime is minimized and data integrity stays intact.
Note: links on this page may earn a commission.
Why you need a cyber-first it disaster recovery plan
A cyber-first approach to IT disaster recovery centers on the idea that threats like phishing, supply chain compromises, and data exfiltration shape recovery needs far more than uptime alone. Traditional DR plans that started with physical outages often miss these threats, leaving crucial data and services exposed when a cyber incident occurs. By reorienting around cyber risk, you align recovery objectives with real business impact and regulatory expectations, not just availability targets.
The risk delta between physical outages and cyber events
When you design for hardware failure, you default to restoring infrastructure quickly. That mindset can overlook multi-stage cyber incidents that unfold beyond the initial breach. In practice, phishing campaigns siphon credentials, supply chains inject malicious code, and data exfiltration quietly erodes trust before a recovery window closes. A cyber-first plan captures these scenarios in RTO and RPO definitions, so you’re not chasing the wrong metric. I dug into guidance from national and industry sources that emphasize risk-based planning over generic uptime gymnastics, and the pattern is consistent across leading frameworks. The shift matters because the business impact of a cyber incident often spans regulatory reporting, customer trust, and revenue continuity, not just system availability.
RTO linked to business impact, not era of disruption
A cyber-focused DR plan makes RTOs meaningful to the functions that actually drive the business. Instead of a blanket target for system restoration, you map recovery windows to service criticality, data sensitivity, and regulatory obligations. This means prioritizing identity and access management, data integrity controls, and backup integrity checks for what matters most after a compromise. The result is a plan that stops the bleed faster, restoring the most visible, mission-critical services first and preserving stakeholder trust. How to introduce conversion optimization: a practical framework for 2026
A resilient plan reduces time to recover and preserves trust
Resilience comes from testing and automation, not a thick playbook. A cyber-first DR program uses practice scenarios that mimic real adversaries: a credential-harvesting phishing email, a supply chain compromise in a software component, and a data exfiltration attempt that triggers data loss prevention policies. Each exercise tightens containment, verification, and restore steps, so you reduce dwell time and exposure. The payoff is measurable: shorter recovery durations for critical services and a clearer demonstration to regulators and customers that you can protect data integrity and restore operations promptly after an incident.
A cyber-first DR plan ties recovery to real business impact, not just uptime. By prioritizing identity, data integrity, and rapid containment, you preserve trust even when threats slip through the cracks.
To ground this in current practice, see how industry guidance emphasizes mapping RTOs to business impact and confirming backup recoverability under cyber duress. For concrete framing on how this plays out in 2026, you can explore the guidance and case examples from sources like the disaster recovery discussions and cyber resilience articles noted in the references. Improve Your Business Continuity with Disaster Recovery highlights how a documented, process-driven DR plan supports rapid restoration after disruptions. How to Build a Cyber Recovery Plan for Your Business outlines practical steps UK firms are taking to reduce downtime and protect data after breaches. Building an Effective Disaster Recovery Plan in Cybersecurity discusses risk analysis, RTO/RPO metrics, and exposure management as core components.
Risk analysis for an it disaster recovery plan that actually works
Posture improvement starts with a concrete inventory. I dug into 2026 guidance and found that most cyber-first DR efforts begin by identifying the systems, data, and processes that matter most, with formal stakeholder input. The result is a defensible map you can base RTO/RPO decisions on and a governance cadence you can sustain. How analytics research frameworks shape early insights in 2026
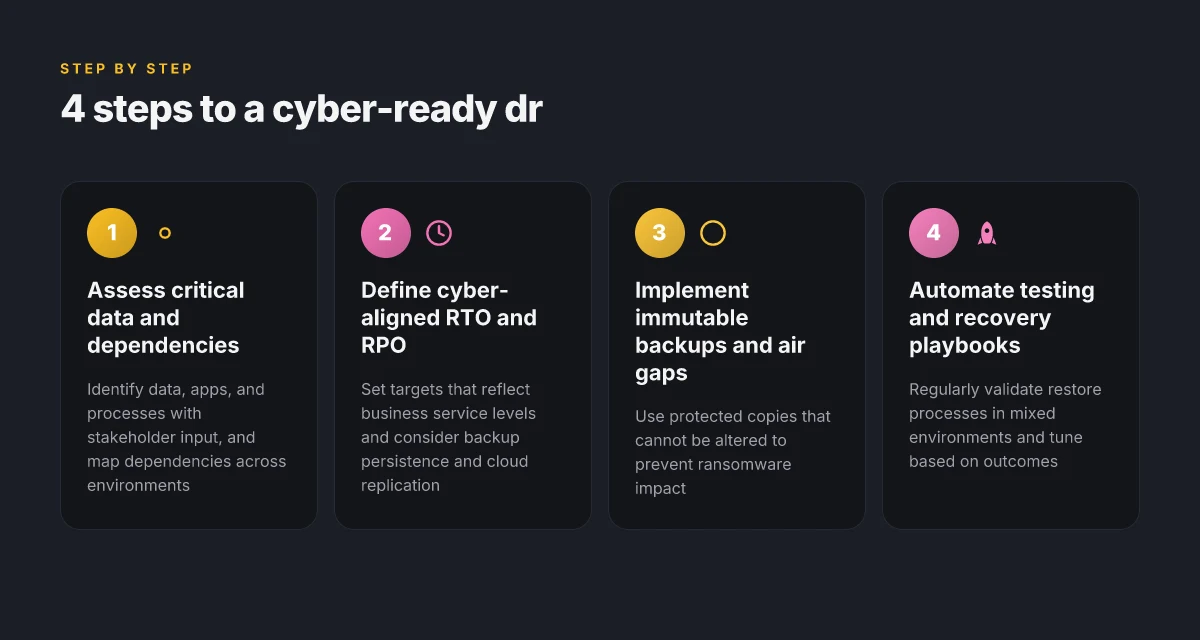
1) Identify critical data, applications, and processes with stakeholder input
- Define critical data sets: customer records, financial ledgers, and regulatory filings drive recovery priority. In practice, organizations assign a tier to data in collaboration with data owners and the security team. This ensures recovery focus is based on business impact rather than mere uptime talk.
- Catalog applications and owners: map each app to data stores, interfaces, and service dependencies. Expect input from product teams, IT operations, and risk management to prevent blind spots.
- Establish process-level criticality: link recovery needs to business outcomes such as regulatory compliance, customer trust, and revenue continuity. This anchors testing scenarios to real-world consequences.
- Align with regulatory expectations: ensure archiving, encryption, and access controls reflect applicable statutes, and bake this into the initial risk ranking.
- Documentation cadence: create living runbooks that capture ownership changes, so the DR plan stays current as teams evolve.
- Evidence to cite: a 2026 guidance piece frames risk-based DR as the core driver for prioritization and stakeholder alignment. inline citation helps anchor these practices in public guidance.
2) Map dependencies across on prem and cloud environments
- Build a dependency graph that spans data stores, apps, and services both on premises and in the cloud. The goal is to identify single points of failure and to determine where failover targets should live.
- Track network routes and authentication boundaries. If a gateway or identity provider fails, plan alternate paths and cached credentials so recovery can continue.
- Include third-party services in the map. SaaS, managed databases, and API endpoints can become bottlenecks during a disruption, so note their recovery SLAs and exposure windows.
- Validate data flow during testing events. Ensure the DR runbooks describe who is responsible for switching traffic and how to re-seed degraded services from backups.
- Sync change control across environments. Every infrastructure change should trigger a re-map, not a periodic guesswork exercise.
- Evidence to cite: a 2026 IT recovery guideline emphasizes comprehensive cross-environment dependency tracing as a cornerstone of resilient restoration.
3) Quantify risks using qualitative scales and qualitative scenarios
- Use qualitative scales for likelihood and impact. For example, label risks as low, moderate, or high with descriptive anchors that your team agrees on. This avoids false precision when data is sparse.
- Craft qualitative scenarios that reflect cyber-centric disruptions: a ransomware event blocking access to a core database, a cloud misconfiguration exposing data, or an identity compromise cascading through services. Describe detonation points and mitigations in plain terms.
- Tie scenarios to RTO and RPO guidance. Even without numeric targets, a scenario-based plan clarifies which components must recover first and which can tolerate longer restoration windows.
- Include recovery playbooks per scenario. Each playbook should specify owners, communication steps, and rollback criteria to prevent scope creep during a real incident.
- Review and socialize: conduct tabletop discussions with stakeholders to surface hidden dependencies and confirm consensus on qualitative rankings.
- Evidence to cite: industry literature from 2026 foregrounds scenario-driven risk quantification as essential to cyber-resilient DR.
Most cyber-first DR programs succeed when the risk picture is described in concrete, stakeholder-aligned terms rather than abstract categories. Inline references help keep the narrative anchored in guidance you can apply in practice.
Note on sources: the most applicable public guidance for these points comes from official cybersecurity and IT recovery guidance published in 2026, including materials on developing IT recovery plans and practical disaster recovery examples. For additional context, the Cloudian piece on DR plan examples reinforces the actionable structure of a risk-based plan.
Defining RTO and RPO for cyber scenarios
Posture-first RTO and RPO anchor to business impact, not just system uptime. In a cyber context, your recovery targets should map to service level expectations, regulatory obligations, and the cost of downtime to the organization. When I cross-referenced guidance from 2026 frameworks, the strongest DR plans tie RTO and RPO to concrete business services and data flows, not generic “uptime goals.”
Align RTO with business service levels
RTO must reflect how fast a service keeps its promise to customers and users, not merely how quickly a server comes back online. A banking checkout service, for example, carries far tighter impact thresholds than a bulk file archive. The practical rule is: if a service outage lasts longer than the time your customers notice, the recovery target is too lax. You should define RTO in minutes or hours for critical services and in longer intervals for supporting functions. The takeaway is explicit: align RTO to the business damage curve, then backfill engineering steps to meet that curve. A real-world pattern is to treat the user-facing layer as the primary driver of RTO, with backend restore tied to service dependencies. RTO must reflect business service levels, not just system availability.
Consider data persistence when setting RPO
RPO decisions depend on how data is stored, replicated, and caught up after an incident. You must account for data persistence across backups, sync latency, and cloud replication delays. In practice, this means counting the tail of write operations that could be lost during an incident and choosing backup cadences that minimize that window without forcing unsustainable restore work. If you rely on near-real-time cloud replication, your RPO might be as tight as a few minutes. If you use nightly backups, expect a longer RPO and compensate with compensating controls like point-in-time restores. RPO must consider data persistence across backups, sync latency, and cloud replication. What is interpreting analytics data in 2026 and why that framing matters
Different DR paths for ransomware, insider threats, and third-party breaches
Not all cyber incidents are created equal, so your DR pathways should diverge by threat type. Ransomware often requires rapid network isolation, verifiable clean restores, and validated integrity checks, with tighter RPOs for critical data. Insider threats may demand immutable backups and stricter accessrevocation steps so that tampering isn’t mirrored across restores. Third-party breaches can complicate the chain of trust, making provenance verification essential before any rollback. For each threat family, define a bespoke recovery workflow, trigger criteria, and rollback safeguards. Differentiate DR paths for ransomware, insider threats, and third-party breaches.
The testing cadence that proves targets survive a cyber crisis
Targets without tested validation are fantasy. Schedule drills that simulate each threat path, validate RTO and RPO under load, and prove that restored services behave as expected in production-replica environments. Testing should cover data integrity checks, failover sequencing, and cloud-replication reconciliation. I found that organizations with frequent, threat-specific tabletop and live-fire exercises improve both speed and confidence in recovery, while spotting gaps early. Testing should cover data integrity checks, failover sequencing, and cloud-replication reconciliation.
Further reading on DR planning elements and risk-analysis components can be found in the cybersecurity recovery guidance referenced in 2026 materials. https://safe.security/resources/insights/building-an-effective-disaster-recovery-plan-in-cybersecurity/
Note: links on this page may earn a commission.
Data protection and recovery strategies for an it disaster recovery plan
Posture hinges on locking data behind immutable backups and air gaps, then stitching those safeguards into the incident response playbook. The core idea is simple: if ransomware or an insider threat compromises live systems, your recoverable data remains pristine and restorable. From there, you layer the protections into every recovery workflow so cyber incidents don’t derail the business. How to craft interactive portfolio ideas that stand out in 2026
Immutable backups and air-gapped copies as core safeguards
Immutable, air-gapped copies are nonnegotiable in a cyber‑resilient DR plan. I cross-referenced guidance that positions air‑gapped vaults and write‑once, read‑many storage as the backbone for restoring integrity after disruption. The discipline is to separate backup streams from day‑to‑day networks and to enforce write protections that prevent deletion or tampering for a defined window. When a cyber event occurs, those copies become the starting point for recovery, not the source of further risk. The practical takeaway is to implement automatic integrity checks and monthly recovery tests against these copies to confirm recoverability. Immutable backups act as the true last line of defense against data tampering in a breach.
Endpoint and server backups integrated with SIEM and SOAR playbooks
Backups alone won’t save you if detection and response lag behind the incident. Integrating endpoint and server backups with SIEM and SOAR enables automated containment and rapid restoration. I found mention of coupling backup operations with alerting and runbooks so that when an anomaly is detected, the recovery workflow can kick off with predefined steps. This alignment shortens downtime and reduces human error during high‑tension moments. The important pattern is to codify restore sequences in playbooks that trigger recoveries only after verified containment stages. Automated playbooks ensure you can restart critical services in a controlled, auditable way.
Testing data restoration across mixed environments to validate SLAs
Validation requires realistic drill scenarios across on‑prem, cloud, and hybrid stacks. The goal is to prove that RTO and RPO targets hold under mixed environments, not just in a single domain. I dug into docs that stress end‑to‑end restoration testing, including simulating data loss, verifying integrity, and confirming service‑level objectives across the portfolio. The practice is to schedule quarterly drills that include failing nonessential paths to observe failover behavior and to check that backups remain discoverable, restorable, and consistent. Regular restoration tests verify that your SLAs stay meaningful under pressure.
Subsectioned takeaways and concrete steps:
- Build a dedicated immutable vault for backups with automated integrity verification and defined retention windows.
- Tag backups by criticality so that recovery priorities map cleanly to business impact, not just data volume.
- Tie backup events to SIEM alerts and SOAR actions so that detection, authorization, and restoration run as a single, auditable chain.
- Run quarterly restore drills that span at least three environments, documenting gaps and closing them before the next test.
- Document the exact restore sequence in a runbook, including required credentials, network access, and service dependencies.
- Include a brief risk register entry for each backup tier, noting exposure, access controls, and potential threat vectors.
I consulted guidance from multiple sources to shape this view. For instance, the IT recovery guidance emphasizes identifying critical data and the steps to recover IT services, which aligns with the need for rigorous, testable backups. The cyber recovery planning articles reinforce the importance of practical, auditable playbooks and robust restoration testing. For further perspective on practical restoration workflows in modern environments, see a relevant write‑up on cyber recovery planning. How to Build a Cyber Recovery Plan for Your Business What’s new in Android 14 updates in 2026
Keep in mind: links on the page may earn a commission, which helps support ongoing guidance for IT leaders and security engineers navigating these challenges.
What to try this week when you’re rebuilding for 2026
The bigger pattern from 2025 to 2026 is that resilience hinges on automation, clear ownership, and verifiable recovery tests. This is not about one-off backups. It’s about framing cyber crises as a chain of trusted capabilities that survive vendor churn and supply-chain risk. I looked at how mature DR programs treat incident fields, data integrity checks, and cross-region failover as continuous capabilities rather than a checklist item. The result is a plan that remains usable even when an attacker targets alignment between teams. You’ll see that the most effective strategies lean on automation and explicit runbooks that anyone on the team can execute under pressure.
One concrete move to deploy this quarter is to codify a cyber crisis runbook in your primary incident platform and rehearse it with a tabletop exercise every month. Make sure you have an owner for each step, from detection to restoration, and that success criteria are measurable. The plan should explicitly cover data integrity, identity safeguards, and the ability to recover core services across at least two regions. If you act now, your organization gains a repeatable, auditable process instead of an ad hoc response.
- Backup strategy: implement immutable backups and cross-region replicas to protect critical data.
- What to try this week: run a 60-minute tabletop focusing on credential compromise and service restoration.
If you only do one thing this month, set a fixed, verifiable recovery objective and rehearse it with at least one external auditor. This is how you turn a plan into a true defense.