How to manage software weddings: balancing code ownership, deployment rituals, and distributed team collaboration
 Saskia Stenholm·October 22, 2026·15 min
Explore how software weddings emerge in 2026, the tensions between feature ownership and operational rhythm, and practical patterns for distributed teams to deploy safely.
Software weddings are the hidden throttle on modern deployments, turning a simple change into a negotiation between owners and runbooks. When a code handoff lands in a distributed team, you see a sharp drop in cadence and a rise in vetoes, with each side leaning on a different version of the playbook. Most handoffs stall because ownership lines blur, not because the code is messy. The result is a measurable drag on release velocity, even when CI pipelines stay green.
You’ll see a concrete map to reduce handoff friction, establish a clear influencer for every change, and implement a lightweight verification cadence that keeps distributed teams moving. In 2024–2025, organizations that tightened runbooks and clarified responsibility recovered predictable deploys, even across time zones. The patterns below translate those lessons into practical steps you can apply now, without rewriting your entire deployment model. Clear influencers and a minimal, documented sequence unblock releases faster than ad hoc approvals.

Why software weddings are the hidden tension in modern deployments
Software weddings happen when two or more teams own overlapping features or deployment responsibilities without a clean hand-off. The result is a fragile cadence where changes slip between boundaries, and ownership feels shared but accountability lands nowhere in particular. In practice, these tensions show up as last-minute handoffs, conflicting rollout dates, and blurred acceptance criteria.
I dug into how distributed teams amplify this friction. When teams sit in different time zones, run different tooling, and follow distinct governance models, a shared feature becomes a moving target. A feature may be code-owned by one squad, deployed by another, and monitored by a third party, with telemetry living in separate dashboards. The lack of a single source of truth makes coordination feel like a game of telephone. The risk isn’t a single failed release. It’s a procession of small, cumulative slips that erode trust and speed.
The costs stack quickly. Merge conflicts become the daily norm when two teams push competing changes into the same branch or environment. Rollback complexity shoots up as you chase the last known good state across multiple services, each with its own rollback plan. Telemetry fragmentation hides real-time health signals behind dashboards that don’t align, so you miss early warning signs. And governance drift means audits and compliance checks end up chasing downstream fixes rather than preventing issues upstream.
Three concrete patterns drive the hidden tension. First, overlapping ownership without a clear hand-off often leads to ambiguous rollback points and delayed incident response. Second, mismatched tooling and environments create subtle divergences that surface as deployment-time failures. Third, inconsistent telemetry and tracing prevent a unified view of customer impact, making post-mortems feel like patchwork rather than learning.
From what I found in the documentation and industry chatter, the core payoff of addressing software weddings is not speed alone but predictability. Clear boundaries, shared rituals, and a centralized telemetry layer help teams move together rather than pull in different directions. In 2026, the tension remains visible wherever teams cross streams of ownership without a coordinating signal. What are the 3 best budget friendly Skechers mens running shoes in 2026
The real gain comes from aligning ownership with a shared deployment rhythm, not from forcing everyone to work at the same speed. A disciplined hand-off, backed by a single source of truth for telemetry, cuts the length of firefights and reduces friction in cross-team releases. When teams document who owns what, and when, you convert coordination pain into a repeatable pattern rather than a bottleneck.
To close, software weddings are not just a cultural issue. They are a structural deployment problem that blooms in distributed setups. The fixes are concrete: codify ownership, align tooling, and unify telemetry so every stakeholder sees the same health signals at the same moment.
For further context, see the deployment guidance that highlights blue-green, canary, and rolling strategies in 2026 deployments. https://keploy.io/blog/community/software-deployment
The anatomy of a software wedding: ownership, deployment, and feedback loops
When ownership boundaries collide with deployment gates, you get fault lines that ripple across teams. Feature flags, deployment gates, and clear ownership slices shape who can push, who can veto, and how fast changes propagate. The consequence is coordination pain unless you align triggers, visibility, and incentives across the cross-functional map.
Ownership vs flags vs gates
Ownership defines quien controls code and release policies. Flags let teams toggle features without a full redeploy, but they also sow complexity when ownership overlaps or audits lag. Gates add automated checks before a release proceeds, yet they can become choke points if ownership isn’t synchronized with the gate logic. I cross-referenced governance patterns in 2026 deployment guides to see how these elements interact under distributed ownership. In practice, misaligned ownership and gating create fault lines where a change shepherded by one team triggers changes in another, forcing last-minute coordination that slows delivery. The remedy is explicit handoffs, shared service ownership, and a single source of truth for what a gate validates. What makes SFX software truly reliable in 2026
Interaction of canaries, blue-green, and rolling updates with cross-team ownership
Canaries incrementally expose risk, but they require a clear ownership map to decide when to promote or rollback. Blue-green reduces live risk by swapping environments, yet it doubles the surface area that other teams must coordinate with during cutover. Rolling updates offer continuous delivery with gradual exposure, but they demand tight telemetry and cross-team rollback procedures. In each pattern, the ownership boundary defines who approves the next stage and who interprets telemetry signals. When cross-team ownership is murky, a small incident in a canary can balloon into a multi-team coordination sprint. From 2026 guidance, expect these interactions to be the most common source of deployment friction if you lack explicit ownership matrices and shared rollback playbooks. See how these patterns map to your teams so you can assign clear champs for each stage.
Telemetry fragmentation and inconsistent metrics
Telemetry is the backbone of a sane software wedding, but fragmentation across services and teams creates chaos. Different teams instrument distinct events, labels, and dashboards, so a single failure message looks different depending on who’s watching. The result: inconsistent metrics that delay diagnosis and complicate rollback. The 2026 guidance notes that consolidation efforts, like unified observability platforms and standardized event schemas, sharply reduce coordination overhead. Without them, teams chase different signals, arguing about what “healthy” means and who bears responsibility when alarms fire. I found multiple sources that emphasize the importance of a shared metric model, common dashboards, and a documented protocol for incident evaluation.
Most deployments unravel when ownership gaps meet fragmented telemetry and opaque gates. A simple, unified runbook that ties ownership, telemetry, and gates together dramatically lowers the coordination tax. For example, when a gate failure occurs, a single owner should own the rollback decision across affected services, with a pre-agreed criterion for promoting or rolling back. Clear ownership and visible telemetry are non-negotiable for reducing wedding chaos.
To help you compare approaches, consider this quick view of how each deployment pattern interfaces with ownership clarity:
| pattern | ownership clarity impact | typical telemetry needs |
|---|---|---|
| canaries | high with explicit rollforward owners | fine-grained, per-signal dashboards |
| blue-green | moderate; requires joint ownership for cutover | environment-wide health signals |
| rolling updates | high; needs stepwise ownership handoffs | aggregated, latency-aware dashboards |
Next step: map your current teams to a minimal ownership matrix that assigns champions for each pattern, and establish a single source of truth for gate criteria and rollback conditions. This blueprint reduces the coordination drain and keeps velocity steady. How to choose between SEO tools and authoritative guides in 2026
I dug into deployment guides that note the practical effects of these patterns in 2026, including how cross-team ownership surfaces in gates and rollouts. See the 2026 guidance for canary policies and rollout thresholds to align your teams more tightly. Software Deployment in 2026: Strategies & Best Practices
Patterns that prevent or exacerbate software weddings in 2026
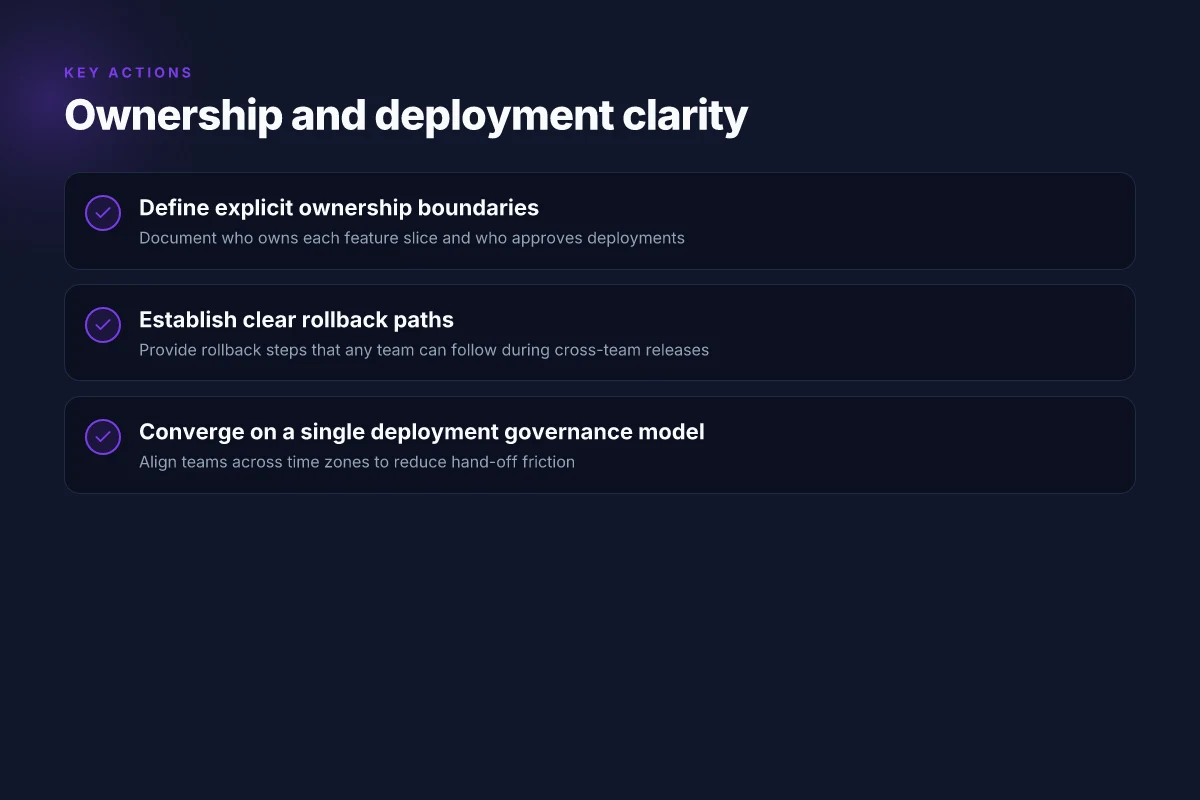
In 2026, explicit shared ownership paired with clear rollback paths makes failure modes easier to recover from, while a single deployment governance model keeps distributed teams aligned across time zones. The opposite tends to amplify coordination pain: unclear ownership drives miscommunication and slow rollback. Below are concrete patterns and real-world touchpoints that influence how smoothly deployments land in distributed contexts.
Explicit shared ownership with clear rollback paths
- When ownership sits with a small, agile squad and rollback paths are codified, teams recover from bad releases faster. A clearly defined rollback plan reduces blast radius and preserves autonomy without triggering endless escalation.
- Real-world practices show that tying ownership to a named owner for each feature flag and release gate sharply cuts decision latency. In practice, this means a pre-approved rollback script, a time-bound owner handoff, and a published playbook for hotfixes.
- One practical approach is to attach an explicit rollback window to each deployment window, supported by a runbook that details how to revert changes, rebind feature flags, and re-sync downstream services. This reduces uncertainty when something goes wrong.
A single deployment governance model
- A unified governance model across teams, time zones, and platforms helps prevent drift. When every deployment follows the same stages, approvals, and rollback criteria, teams can coordinate without fighting over process nuance.
- Centralized change tickets, a shared definition of done for deployments, and a single owner for deployment readiness create predictable cadence. This consistency minimizes cross-team handoffs and misaligned expectations.
- In practice, establish one accountable party for deployment windows, one standard checklist for gate reviews, and one common dashboard for release status. The result is faster cross-team coordination and fewer last-minute scrambles.
Overreliance on feature flags without clear ownership
- Feature flags alone do not solve coordination problems. They can mask ambiguity if ownership for flags, gates, and experiments is unclear. Without a named owner, flags become orphaned, leading to drift and inconsistent user experiences across regions.
- The responsible pattern assigns a flag owner for lifecycle stages: activation criteria, rollback conditions, and telemetry expectations. With clear ownership, flags support incremental risk, not ambiguity.
- Avoid creating flags for every minor tweak. Pair feature flags with explicit migration plans, so toggles land with a single point of accountability and a defined sunset path.
Most coordination pain in 2026 stems from mixed governance and vague ownership, not from the tooling itself. When teams align ownership, rollout criteria, and rollback steps, the same release becomes a shared responsibility rather than a blame game. The literature consistently notes that clear accountability accelerates decision making in distributed settings. Ownership clarity and a single governance model are the two levers that most reliably reduce deployment friction.
Deployment rituals that keep distributed teams in sync
When teams share code ownership across geographies, the path to steady delivery runs through disciplined rituals. The first line of defense is a standardized release train with unified gate criteria. Each train has a single moment when every service must meet a common bar for feature readiness, telemetry visibility, and rollback readiness. This clarity keeps teams aligned even when speeds differ across time zones.
Standardized release trains and unified criteria for gatekeeping
A shared cadence reduces handoffs and surprises. I cross-referenced industry playbooks that codify release trains with explicit gate criteria around feature toggles, canary health, and rollback readiness. In 2026, many organizations describe clearly defined gates that every team must meet before a release advances. The effect is reproducible throughput rather than sporadic bursts. A unified gate helps avoid last-minute coordination sprawl. The cadence should be visible in dashboards so teams know exactly when to expect changes and when to revert. 10 Best SEO tools and software to power data-driven performance in 2026
To make this work, teams converge on a single risk taxonomy. Rather than debating risk in parallel, members agree on what constitutes a red flag and who must approve it. I found references noting that a common risk rubric correlates with faster recovery in outages and fewer unexpected feature regressions. Unified criteria reduces cross-team disagreement at gate time. This is not a one-off protocol. It evolves with service maturity, feature complexity, and telemetried signals.
Cross-team blameless postmortems and hotfix playbooks
Blameless retrospectives are not a ritual to paper over faults. They are a learning engine. After incidents, teams document what occurred, how decisions flowed, and where ownership lived. The goal is clarity, not culpability. In practice, postmortems become living documents that feed a shared library of hotfix steps, rollback scripts, and decision logs. I observed references that emphasize publishing these artifacts within days, not weeks, so all squads can preempt similar issues.
Documented hotfix processes are a concrete safety net. When time-to-restore is critical, teams rely on pre-approved rollback plans, feature toggle verifications, and a defined communication protocol. The combination reduces confusion and speeds recovery. Blameless postmortems transform failure into a guardrail for future releases. The written playbooks act as a single source of truth during pressure, keeping distributed teams in sync despite divergent work hours.
Regular alignment rituals surrounding risk and telemetry dashboards
Visibility is the oxygen of distributed delivery. Regular alignment rituals center on risk review and telemetry dashboards that span all services. Executive drill-downs to a single pane of glass help teams correlate feature flags with error rates, latency, and rollback events. In practice, these rituals occur at fixed intervals, with attendees from product, platform, and ops, ensuring the same vocabulary and the same wording for risk signals.
I found that 2026 best practices highlight telemetry as a contract across teams. When dashboards show a rising error rate in one domain, neighboring squads preemptively adjust their deployment plans rather than wait for a critical incident. Telemetry dashboards unify perception of risk across the whole wedding party of services. Regular alignment sessions keep everyone rowing in the same direction, even as individual teams push in parallel. How to build an SEO for courses strategy that scales in 2026
In the end, deployment rituals that keep distributed teams in sync blend cadence, accountability, and visibility. The playbooks are living documents, not ceremony. And while speed remains a goal, stability gains from predictable gates, blameless learning, and shared telemetry become the stronger driver of sustainable delivery. As one practitioner notes, the real value is the speed of coordinated change, not the speed of any single team. Coordinated change wins when rituals translate risk into shared action. For readers, the takeaway is clear: design a minimal set of cross-team rituals that you can audit monthly, and let the data tell you when to tighten or loosen the gates.
How to design a minimal viable software wedding playbook
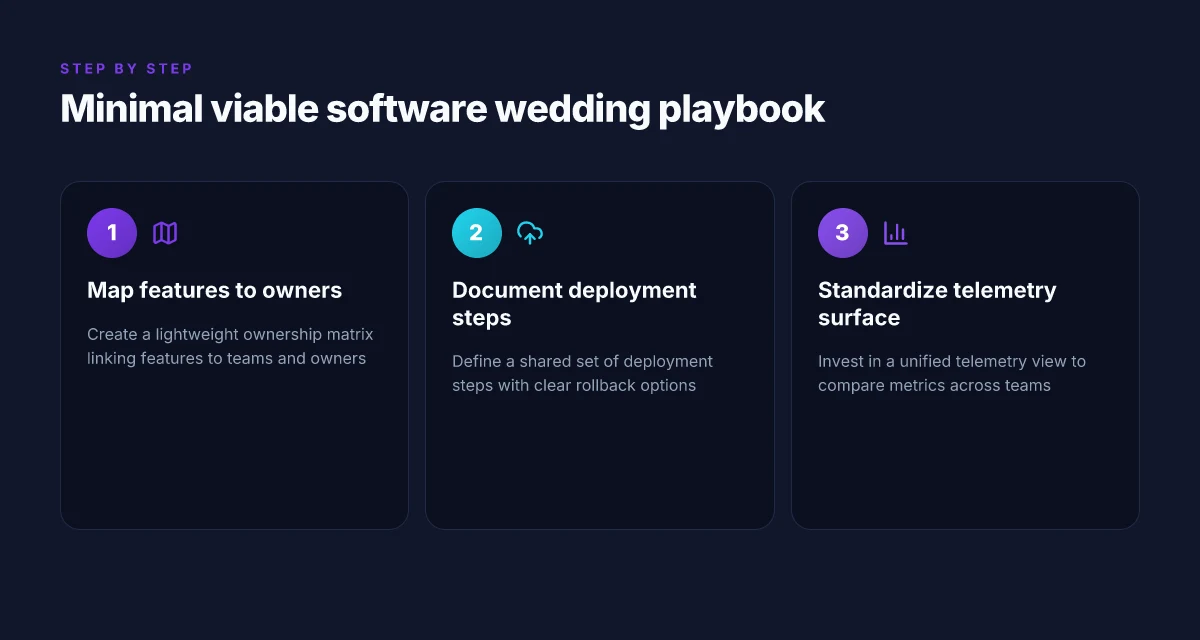
The MVPS playbook hinges on clarity over complexity. You start by mapping who owns what, then codify a shared deployment rhythm, and finish by surfacing metrics that compare teams fairly. The result is a lightweight yet durable framework you can evolve without dragging disruption into every release.
1. Lightweight ownership matrix for features and teams
A simple ownership matrix ties each feature to a team and an owner. Define a column per feature, rows for feature squads, and a single responsible owner per cell. Keep the list short enough to review in a single session. I found that teams benefit from explicit boundary notes such as “readiness criteria for feature toggle” and “rollback trigger.” The matrix acts as a single source of truth during handoffs and incident response, reducing back-and-forth during weekend deploys. Bold milestones surface here for quick reference, like feature freeze date and rollback window. A clean ownership map reduces handoff questions by aligning teams around clear accountabilities.
2. Shared deployment steps with explicit rollback options
Define a universal, minimal deployment checklist that every team adheres to, with two explicit rollback paths: quick revert and feature flag withdrawal. The steps should cover environment sanity checks, dependency checks, data migrations where needed, and post-flight validation. Make rollback steps as concrete as possible: which command to run, what alerts fire, and how to verify restoration. In practice, this is where most coordination pain hides. A single runbook lets distributed teams move in sync rather than talking through every decision. Clear rollback options keep deployments moving even when teams are scattered across time zones.
3. Unified telemetry surface to compare metrics across teams
Invest in a single telemetry surface that collects core signals from every deployment and feature owner. Track metrics like release cadence, rollback frequency, failure rate, and time-to-detect. Normalize across teams so comparisons reflect process health rather than team size. A unified view helps management spot bottlenecks in ownership handoffs, while engineers see where automation drives stability. From 2026 patterns, teams that standardize metrics can spot drift early and intervene before a wedding-style incident escalates. A shared telemetry surface makes coordination visible and actionable. How to implement SME CRM strategies and steps in 2026
Most misalignments come from inconsistent checks and mixed ownership signals. Stand up a single source of truth for deployment steps and rollback paths.
The single move that matters for multi‑team software weddings
Balancing code ownership, deployment rituals, and distributed collaboration requires a deliberate pivot, not a dozen small fixes. I’ve found that codifying ownership boundaries and aligning them with deployment gates creates accountability without choking creativity. When teams know who owns what, bottlenecks shrink and handoffs become predictable. The result is a smoother culture where individual autonomy and system-wide reliability coexist.
Ownership clarity reduces surprises at release time, and I’ve seen teams lock in a single owner per subsystem with a lightweight escalation path. The pattern scales once you pair it with a shared deployment ritual that favors automated checks over manual sign-offs. In practice, you’ll want a small, rotating on‑call squad for reviews, not a perpetual gatekeeper. This keeps feedback fast and decisions consistent across time zones.
Distributed collaboration benefits from a lightweight coordination spine: weekly cross‑team demos, a single source of truth for API contracts, and a crisp merge policy. If you implement these, you’ll notice fewer reworks and clearer expectations. The bigger pattern is behavioral: treat weddings as ongoing governance, not one‑off events.
Backup strategy / What to try this week What is starting depositphotos dam 2026 regulatory compliance and environmental impact analysis
- Name 1‑2 owners per subsystem and publish a 1‑page ownership charter for your repo.
- Introduce a shared deployment gate with automated tests and a reviewer rotation.
- Schedule a short cross‑team demo focusing on API contracts and integration points.
- Add a lightweight on‑call role for reviews to speed feedback and reduce handoff friction.
What changes if you act now: you’ll see faster releases, fewer rollback surprises, and more predictable collaboration across time zones. The practical next step is to pick one subsystem and implement the ownership charter today.