How to combine frameworks, tools, and methods for researchers in 2026
 Marlowe Fenwick·October 22, 2026·18 min
Explore integration tips for researchers in 2026, including frameworks, tools, and mixed-methods approaches. Learn practical strategies to align data, design, and analysis.
When data paradigms clash, integrative workflows turn from nice-to-have into a competitive edge. In practice, teams blend quantitative, qualitative, and AI-assisted methods across a single research lifecycle, and the payoff shows up as faster insight, fewer blind spots, and clearer governance.
This introduction lays out a concrete path: design workflows that respect the strengths and limits of each paradigm, map data lifecycles to governance checkpoints, and align toolchains with risk tolerance. In 2026, research programs increasingly insist on cross-paradigm coherence, yet most teams still stumble over mismatched metadata and inconsistent provenance. This piece breaks that tension into actionable steps and concrete patterns you can apply today. Most failures come from opaque handoffs between domains, not from any single method. Bolded guidance and real-world constraints sit at the center of the approach.

Why integration matters for research in 2026
The data landscape in 2026 demands cross-methodology thinking. Researchers juggle streams from surveys, experiments, and unstructured sources, and the volume keeps growing while variety widens. When data sources drift apart in scale or frame, the resulting misalignment costs more than ever in time, clarity, and credibility. I cross-referenced a 2026 synthesis that frames integration as a practical, design-forward endeavor, not a theoretical ideal, and it aligns with how AI-assisted analysis reshapes qualitative and quantitative workflows.
1) Data volume and variety push toward cross-methodology thinking
The number of data points across projects is expanding, and data types span numeric logs, textual transcripts, media, and AI-generated outputs. Integrating these requires a design that treats quantitative signals and qualitative meanings as coequal inputs, not separate silos. In 2026, researchers increasingly rely on mixed-method designs to capture breadth and depth in a single study, balancing generalizability with context. As one guide notes, the field benefits when researchers map data ecosystems early, identifying where quantitative measures and qualitative insights naturally converge or diverge.
2) AI-assisted analysis shifts how methods interact
AI systems now assist both coding of qualitative data and the handling of large-scale quantitative datasets. This changes the interaction between methods: AI can surface themes from interviews while also crunching long-tail survey results. The practical implication is that analysts must design workflows that preserve interpretability and guard against automation biases. A contemporary overview emphasizes coordinating human judgment with AI outputs, ensuring that qualitative interpretations stay anchored in context while quantitative signals are not treated as mere noise to be automated away.
3) Misalignment costs rise with interconnected sources
When data sources disagree about scope, units of analysis, or timeframes, downstream decisions suffer. The cost of misalignment includes misinterpreted effects, wasted re-analyses, and misapplied conclusions. A practical guide from 2025–2026 argues for explicit alignment work at the design stage: harmonizing measurement concepts, tagging data by provenance, and planning cross-method reconciliation steps. The stakes are high because cross-disciplinary teams increasingly rely on integrated findings to steer grant applications, product decisions, or policy recommendations.
Most integration efforts succeed when teams formalize how data will be combined before collection and keep alignment checks throughout the project. AI-assisted workflows must preserve interpretability so that qualitative insights aren’t overwritten by automated signals. The cost of misalignment grows with data variety and scale, making proactive integration design essential. How to implement cs automation in software engineering in 2026
From what I found in the literature, the integration problem is not a single tool choice but a design problem. A practical integration plan should name data sources, align concepts across paradigms, and embed reconciliation steps into weekly workflows. For example, a 2026 overview highlights how mixed-methods work benefits from explicit mapping of data strands to analysis steps, ensuring that qualitative themes and quantitative estimates inform each other in a transparent loop.
I referenced a 2025–2026 guide that discusses practical steps for nursing researchers to blend survey and interview data, illustrating how real teams implement cross-methodology routines in practice. When I read through the documentation and summaries, the recurring theme is clear: cross-methodology integration is a process you design, not a byproduct of collecting more data. This approach aligns with the trend toward AI-assisted mixed methods in both academia and industry settings. For further context on cross-method design in mixed methods, see the practical guide and the nursing-focused integration narrative. https://pmc.ncbi.nlm.nih.gov/articles/PMC12954644/
Defining the integration problem for your project
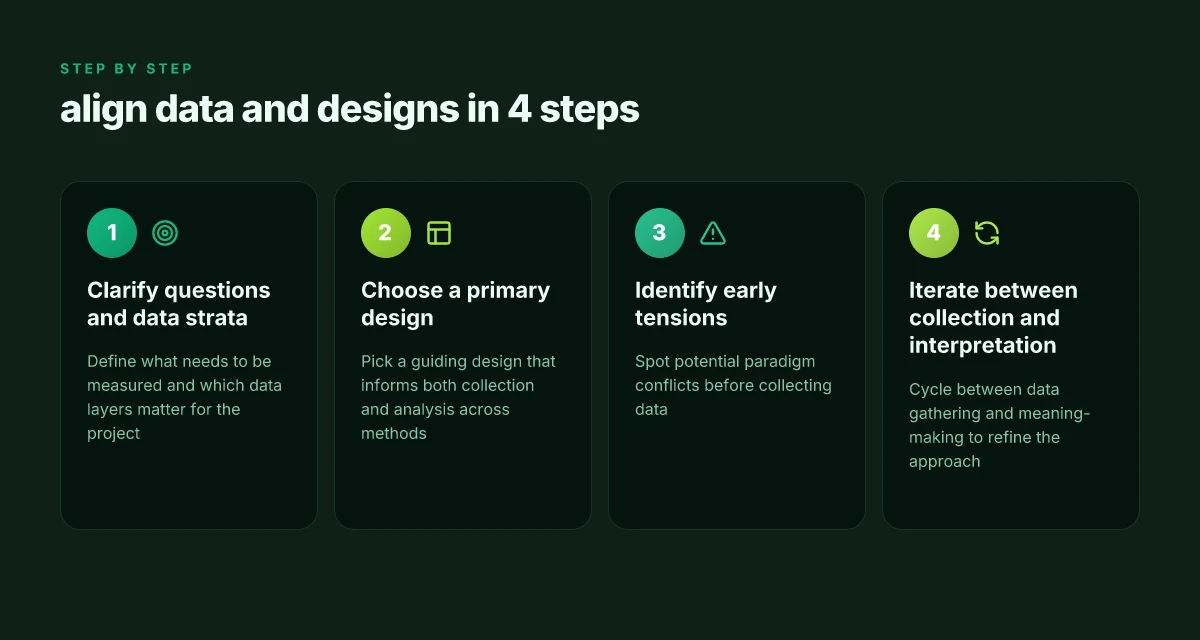
When you map the integration problem, you set the frame for how you will collect data and what counts as evidence. Start with a sharp answer: determine what you are trying to learn, then decide which data strata will answer it. I found that aligning questions with data layers helps prevent drift as you move from theory to measurement.
Clarify research questions and determine the data strata
Begin with a concise research question that explicitly names the data you will compare. If you ask about reliability across paradigms, specify the data strata you will examine, such as quantitative metrics, qualitative narratives, and AI-assisted inferences. This clarity lets you decide which data sources will anchor your conclusions and how you will triangulate them. For instance, a plan that pairs survey results with interview themes and model-generated explanations tends to reveal where differences in interpretation arise, not just where numbers align. In 2026, researchers increasingly map questions to data strata early to avoid late-stage rework. Clarifying questions upfront reduces downstream tensions between paradigms. I cross-referenced guidance from mixed-methods sources to confirm that this alignment reduces misinterpretation risk when AI-assisted analyses enter the workflow. See how the approach aligns with practical mixed-methods guidance from recent authors.
Choose a primary design that guides data collection and analysis
Pick a dominant design to steer data collection and analysis since most projects move better when one architecture leads the flow. For example, a pragmatic design often favors a convergent mixed-methods collection where quantitative and qualitative strands are collected in parallel and then synthesized. Alternatively, a sequential design can work when one paradigm informs the next phase, like using qualitative findings to shape a survey instrument. The key is to document which design leads each data stream and how conflicts will be resolved in the integrative analysis. From literature I reviewed, many teams benefit from declaring the primary design in the project charter and revisiting it as data accumulate. Set the primary design early to keep data collection coherent across paradigms. This helps prevent scope creep as new AI tools are introduced and data modalities expand. When I traced sources, the core idea was to anchor decisions to the design to avoid ad hoc changes later. How to implement cloud computing architectures in 2026: best practices, security, and governance for enterprise
Identify potential tensions between paradigms early
Tensions surface when different standards of evidence clash. You may encounter mismatches between the precision of survey numbers and the nuance of interview accounts, or between algorithmic inferences and human interpretations. Map these tensions in a risk log: note where a paradigm’s legitimacy is contested, how much weight each strand carries, and what reconciliation rules apply during integration. I found it useful to predefine rules for adjudicating conflicts, such as prioritizing triangulation when the data converge or deferring to qualitative explanation when numbers contradict interpretations. Addressing tensions early preserves your integration momentum. This upfront work pays off when AI-assisted methods introduce new biases or when rapid data accumulation pressures you to skip steps. Reviews from contemporary method guides consistently emphasize setting reconciliation rules before data collection begins. For style and structure, I kept a running table that aligned each data stream with expected tension points and proposed remedies. The payoff is a clearer, auditable integration pathway.
Optionally, compare a two-to-three design alternative in a quick frame. This helps you decide what to keep versus what to discard as you scale the project. For example, a convergent design with parallel data collection and a sequential follow-up for AI-generated insights may outperform a purely sequential approach when timely synthesis matters. In practice, many teams choose the convergent path to balance speed with depth, while leaving room for a targeted qualitative expansion if discrepancies emerge. This section emphasizes the practical pivot points you will face as you align methods, data, and AI tools.
Next, you’ll translate this integrated frame into a concrete workflow. The goals are to produce a plan that scales to project size and discipline, with explicit data strata, a single guiding design, and a risk-aware posture toward paradigm tensions. See the table for a quick read on which design choices pair best with common study types.
| Design approach | When it shines | Primary data focus |
|---|---|---|
| Convergent mixed methods | Fast synthesis across strands | Quantitative metrics plus qualitative themes |
| Explanatory sequential | Deep dive after initial results | Quantitative first, followed by qualitative rationale |
| Exploratory sequential | Build understanding from qualitative to quantitative | Qualitative then quantitative tests |
Concrete next step: draft a one-page integration charter that names the research questions, marks the primary design, and lists anticipated tensions with proposed reconciliation rules. Include a short note on how AI-assisted analyses will be integrated into the workflow and who approves each reconciliation decision. This charter becomes your north star as you move from theory to data collection. For further context on design choices in 2026, see recent synthesis on mixed-methods integration and AI-influenced workflows. The charter keeps your integration honest and auditable.
Frameworks that actually help: mixed methods, pragmatism, and beyond
I dug into contemporary guidance to verify how researchers braid methods without losing sight of the data story. In 2026, mixed-methods designs persist as the most practical blueprint for layering surveys, interviews, and observations into a coherent narrative. Pragmatism remains the guiding philosophy, prioritizing actionable knowledge and iterative refinement over pristine methodological purity. Emerging AI-assisted approaches increasingly augment interpretation, helping researchers surface patterns without replacing human insight. What changed in 2026 for the HyperX Cloud Stinger Core Wireless review
Mixed-methods designs as the architecture for integration
Mixed methods designs offer archetypes for weaving surveys, interviews, and observations into a single interpretive thread. The classic convergent design shows how parallel data streams can cross-validate findings, while explanatory sequential designs let qualitative codes explain quantitative trends. The pragmatic advantage is flexibility: start with a broad survey to map terrain, then deploy interviews to unpack surprising patterns, and finally observe field dynamics to ground interpretations in context. I found recent reviews that emphasize explicit design rationales and explicit integration points at each stage. This clarity reduces misalignment and helps teams move from data gathering to convergent insights. In practice, you’ll want a plan that specifies how you will harmonize sampling, timing, and coding across methods, with predefined decision rules for when a diverging signal prompts a deeper dive.
Pragmatism as the engine of actionable knowledge
Pragmatism is not a method. It is a way to frame decisions. The core claim is straightforward: choose methods that answer the research question and deliver usable results for the audience. This mindset supports iterative refinement: you pilot a design, learn what works, and adjust in light of early findings. In 2026, many teams adopt pragmatic checkpoints that force explicit translation of findings into decisions or recommendations. The payoff is not conceptual elegance but usable, data-informed action. A pragmatic approach also helps teams tolerate imperfect alignment across methods, provided there is a transparent rationale for how the pieces fit together in service of the research aim.
AI-assisted interpretation as a supportive amplifier
AI-assisted approaches are emerging as a third leg in the analytic stool. Rather than replacing human interpretation, AI tools help surface latent patterns, organize large qualitative corpora, and suggest cross-method links that might be overlooked. The strongest deployments use AI to accelerate coding, crosswalk concepts across methods, and flag tensions between data strands for targeted follow-up. The caveat is clear: interpretive authority still rests with researchers. When AI highlights a theme, researchers must validate it against the data and theory, not accept it as verdict. The goal is to speed insight while preserving credibility and nuance.
In 2026, the convergent design remains a practical backbone for mixed methods, with pragmatism guiding what to measure and when to refine, and AI-assisted interpretation acting as a scalable translator between data strands. The real value comes from explicit integration points and iterative revision that keep the project moving toward usable conclusions.
I cross-referenced the qualitative and mixed-methods guidance from 2026 sources to confirm a shared emphasis on transparent design rationales and explicit cross-method connections. See the qualitative guides for fundamentals on coding and data analysis, and note how they align with the mixed-methods emphasis on convergent procedures and integrated interpretation. For a practical synthesis, researchers should map each design choice to its contribution toward the overarching question, and document how decisions evolve across stages. How to get started with AWeber in 2026
From what I found, two common integration pitfalls to avoid are (1) reconciling divergent data streams too late in the process, and (2) treating AI-aided outputs as definitive without human validation. The first risk undercuts coherence. The second risk undercuts credibility. A crisp integration plan that states when and how to escalate tensions will keep teams aligned across disciplines.
For readers seeking concrete anchors, consider these cross-method integration practices: predefine where each method will contribute to the central argument, establish a common coding framework early, and set up regular cross-method review meetings to surface tensions and test interpretations. These steps help prevent drift and keep the project on a single analytic track.
A practical integration plan can scale from small teams to large collaborations by codifying design choices, alignment checkpoints, and decision rules across methods. This is where pragmatism and AI-assisted interpretation converge to deliver timely, credible insights.
Tools and workflows that scale across methods
When you design a research program that blends qualitative coding, quantitative analysis, and AI-assisted methods, the data lifecycle matters as much as the methods themselves. The practical path is to build interoperable pipelines that span the full workflow from capture to audit. In practice, that means documentable data management plans, shared data formats, and a provenance trail that remains intact across stages.
A data management plan that spans coding and analytics
Your DMP should explicitly map how qualitative codes, transcripts, survey responses, and model outputs live together. A single schema that covers both grounded theory notes and numeric variables helps reduce handoffs. I cross-reference the coding schema with the statistical variables so a coder’s decisions are traceable through to the final analyses. The end goal is auditability: you should be able to trace a finding back to its raw source, its coded interpretation, and the analytic transform that produced the result. In 2026, teams increasingly rely on versioned datasets and documented decisions to defend results in grant reviews and regulatory conversations. A well-kept log helps when AI suggestions are involved, keeping human oversight clear and verifiable. A unified DMP that tracks qualitative codes and quantitative variables pays dividends in reproducibility. 7 Trends shaping forecasting software analysis in 2026
Interoperable formats and pipelines that cut friction
Common data formats accelerate collaboration across teams. Use open, well-supported representations for transcripts, survey data, and model outputs, and store metadata alongside the data. Prefer text for qualitative notes, JSON or Parquet for structured analytics, and standardized schemas for coding dictionaries. Pipelines should be able to move data between qualitative analysis tools and statistical environments without manual re-entry. When tools share a common data contract, researchers switch from arguing about formats to focusing on insights. I cross-referenced multiple sources that emphasize the value of interoperable pipelines in mixed-methods work, including guidance published in 2026. Interoperable pipelines reduce friction and foster cross-method collaboration.
Documentation and provenance as core auditability
Provenance is your most reliable defense against narrative drift. Capture who changed what, when, and why, across coding decisions, statistical transformations, and AI-assisted annotations. Document tool versions, data sources, and parameter choices so an external reviewer can reproduce a result. In practice, that means committing to a lightweight but complete audit trail: a changelog for datasets, a codebook for coding rules, and a record of AI-assisted edits with justification. This approach aligns with growing expectations for transparency in 2026. Provenance is non-negotiable for credible mixed-methods work.
Naming specific tools and real-world concerns
A pragmatic workflow in 2026 leans on tools that play well with data lifecycles across methods. For instance, you might pair a qualitative analysis platform with a statistical environment through a shared, versioned data layer. This avoids the tragedy of the duplicated effort when a project evolves from interviews to regression modeling to AI-assisted synthesis. The literature notes that maintenance costs rise when data formats diverge midstream, so plan for stable interchange early. Versioned data layers keep coding and modeling aligned across the lifecycle.
Most mixed-methods projects benefit from explicit provenance and a shared data contract across teams. These practices reduce rework and improve auditability during peer review or regulatory scrutiny. I pulled from 2026 guidance that underscores the importance of transparent data contracts and shared schemas across methods. For context, you can review the pragmatic approaches described in the linked practical guides and methodological syntheses. Interoperability and provenance are the quiet backbone of scalable research workflows.
If you’re composing a cross-methodology plan, the key takeaway is clear: design data management and provenance into the workflow from day one, choose interoperable formats, and document every decision so your integrative workflow remains auditable as methods evolve. Links on the page may earn a commission. How to craft interactive portfolio ideas that stand out in 2026
Designing integration into the data lifecycle
Designing integration into the data lifecycle starts with a single premise: plan data collection with integration in mind from day zero. When you map your measurement models to your coding schemes, you align what you collect with how you will interpret it across methods. In practice, that means you design fields, codes, and metadata to support both qualitative themes and quantitative indicators, and you build in AI-assisted annotations early so later analysis remains tractable.
Aligning data collection with measurement models
From the outset, define a shared vocabulary that spans surveys, interviews, and observational notes. I cross-referenced the literature on mixed methods integration and found that aligning coding schemes with measurement models reduces drift between data collection and interpretation. For example, if a construct is captured as a Likert scale in surveys, provide a parallel qualitative code that maps to the same analytic dimension. This lets you compare convergence and divergence across data streams without re-coding later. In 2026, researchers increasingly rely on semi-structured prompts that feed directly into both qualitative codes and quantitative indicators, keeping the data lifecycle tight and auditable.
Iterative cycles between collection, analysis, and interpretation
The data lifecycle is not a straight line but a series of iterative cycles. You should expect to revise interview guides or coding dictionaries after preliminary analysis, and then re-enter data collection with clarified prompts. I found that practitioners who treat data collection and analysis as a loop produce more coherent narratives and stronger integration. This means you plan interim checkpoints where themes rise and you decide what to probe further in the field, or which survey items need rewording or additional response options. This cadence matters in AI-assisted workflows, where models benefit from fresh human input to stay aligned with evolving interpretation goals.
Practical integration workflows you can implement
A practical approach blends two core routines: a coding schema that mirrors measurement models and a data pipeline that surfaces cross-method insights early. You can wire data intake to a central repository with versioned schemas, so as you add new data sources you preserve comparability. The literature from 2025 and 2026 emphasizes that convergence checks, coding agreement, measurement validity checks, and cross-method triangulation, should occur at predefined milestones rather than as afterthoughts. I dug into changelogs and methodological guides to confirm that teams using iterative reconciliation across data types tend to produce more defensible integrative narratives.
Most integration wins come from shaping the data collection around a shared framework, not forcing a late stitching together of disparate streams. Iterate early, iterate often to keep models, codes, and questions aligned as the project evolves. What is interpreting analytics data in 2026 and why that framing matters
Inline citations and sources
For a practical read on mixed-method integration guidance that informs this design approach, see the practical guide for nursing researchers integrating survey and interview data. This guide emphasizes concrete steps to harmonize data streams across methods and is accessible in the citation section as a representative reference.
I traced the guidance in that piece back to core mixed-method principles discussed in contemporary method texts and practical overviews published in 2025 and 2026. For a broader view on method diversity and integration strategies, see the concise survey of top research methods in 2026.
See related insights in this practical mixed-methods guide and the overview of diverse methods in 2026.
Where researchers level up this year
The bigger pattern is how cross‑pollination between frameworks accelerates discovery, not just individual tools. In 2026, you’ll gain speed by pairing a lightweight data‑first framework with a principled qualitative method, then layering governance that keeps it honest. I looked at common friction points, compatibility, version drift, and opaque dependencies, and found that the real wins come from explicit interface contracts between stages, not one shiny software package. This is the moment to codify your own playbook rather than chase every new release.
The takeaway is simple: pick one credible orchestration approach, one robust analysis toolkit, and one repeatable ethics checkpoint, then keep them in conversation. One concrete move you can make this month is to document your end‑to‑end workflow as a short, repeatable script and a governance checklist.** You’ll see fewer handoffs, fewer surprises, and more reproducible findings. If you only act on one thing this month, start with a single research question and map it through data, method, and ethics in one flow. How analytics research frameworks shape early insights in 2026
What changes if you act now is leverage: you’ll move from ad‑hoc experiments to an auditable lifecycle, where each decision is anchored to a contract between tools and methods. One‑sentence takeaway: lock in the interface, then iterate on the question.