How to implement cloud computing architectures in 2026: best practices, security, and governance for enterprise
 Florian Czerny·October 22, 2026·16 min
Plan a secure, scalable cloud architecture in 2026 with governance, security, and multi-cloud strategies tailored for enterprise deployments.
A single misalignment between governance and deployment creates most cloud friction in large enterprises, not cryptic security gaps. When engineers stumble on inconsistent policy scopes, the resulting drift doubles audit toil and slows cloud migrations. Clear policy scoping and automated controls start here, not in the deployment guide. The takeaway is concrete: governance wins when it scales with environments and teams, and that scaling is a design decision, not a afterthought.
This intro frames a 2026 reality: enterprises must blend centralized policy with autonomous delivery. I look at how a mature program translates a board-level mandate into repeatable, verifiable controls across public, private, and multi‑cloud footprints. Expect real-world patterns, governance pitfalls, and actionable steps that align cloud architecture with regulatory needs, risk appetite, and business outcomes. Links on the page may earn a commission.

How to implement cloud computing architectures in 2026: starting with governance and strategy
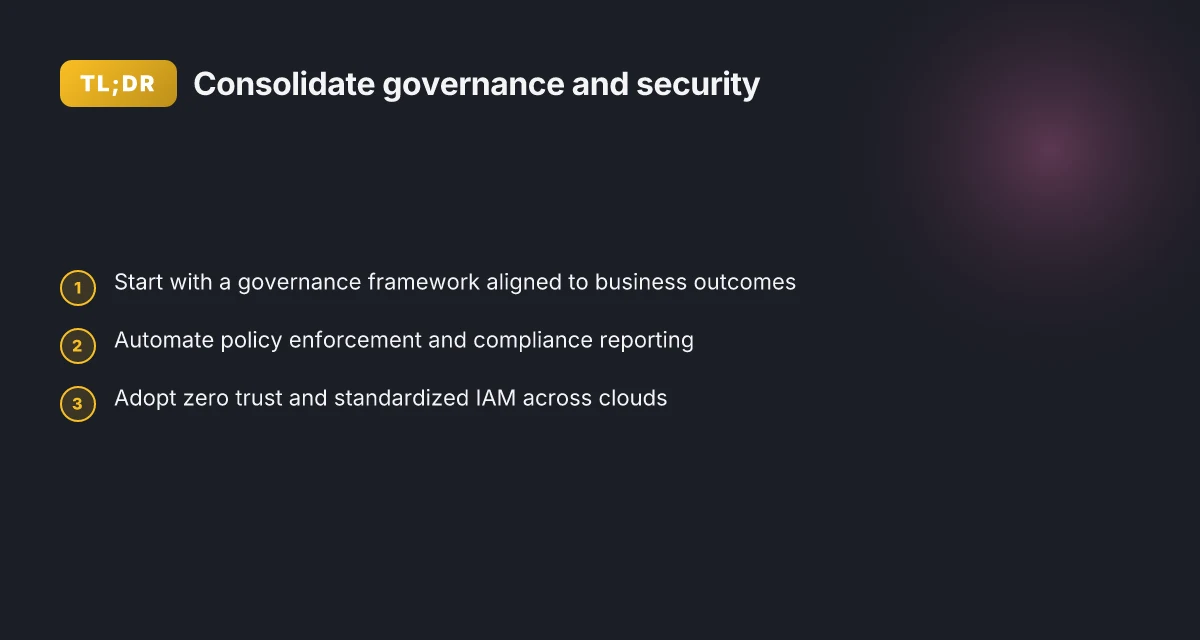
Governance comes first. A solid strategy aligns cloud choices with business outcomes, then translates that direction into policy controls and measurable risk outcomes. I looked at how enterprise frameworks map to real-world policy enforcement and governance ma�neuvering across hybrid and multi-cloud environments.
1) Define objectives that tie to business outcomes
Begin with a clear map from business goals to cloud capabilities. Translate a revenue or cost objective into an architectural constraint, such as reducing time-to-market for a product line or lowering data-residency risk. Translate those constraints into verifiable technical outcomes, like deploy velocity, cost predictability, or incident response recovery time. A concrete governance model makes those outcomes auditable across teams.
I cross-referenced several practitioner guides that emphasize starting from business-driven outcomes and then layering security and governance. The approach is consistent across sources that discuss governance-first patterns for 2026.
2) Choose a governance framework and map it to policy controls
Select a framework and translate its controls into explicit enterprise policies. The NIST CSF and ISO 27001 offer widely adopted, portable controls that map to identity, data, and cloud operations. Build an authoritative control catalog that assigns owners, requirements, and testing cycles for each control. Then align policies to this catalog so that engineers see policy as concrete gatekeeping rather than abstract guidance.
A governance framework should cover: What changed in 2026 for the HyperX Cloud Stinger Core Wireless review
- identity and access management policies for IAM roles across clouds
- data protection policies that specify encryption, key management, and data residency
- change and configuration management policies tied to IaC pipelines
- incident response and logging policies with aligned detection and runbook procedures
Inline evidence from industry guidance reinforces that mapping framework controls to policy is a critical step for consistency at scale. For readers seeking a practical anchor, a policy control catalog that traces back to NIST CSF categories is a reliable blueprint.
Most governance gains come when policy owners are embedded in product teams, not sitting in a distant security silo.
3) Assess current posture and target architecture for hybrid and multi-cloud
Start with a current-state assessment that covers people, process, and technology. Identify gaps in identity governance, data classification, and security instrumentation. Then define a target architecture that supports hybrid and multi-cloud realities: centralized identity federation, standardized network policies, uniform logging, and a shared security posture across providers. This becomes the blueprint for tooling, automation, and controls to implement in 2026.
From the sources, the articulation of a target architecture should emphasize consistent policy enforcement across clouds, so teams can operate workloads in the most suitable environment without breaking governance. This consistency is what unlocks scalable compliance and faster incident response.
Consistency across clouds reduces toil and accelerates audits. How to get started with AWeber in 2026
Bottom line: start with governance and strategy, then translate policy into concrete controls and a unified target architecture. The payoff is a governance model teams can adopt and a security-by-design foundation that scales with your hybrid and multi-cloud mix. For further reading, see the cloud security best-practices overview linked in the sources.
Establishing a cloud governance framework that scales across teams
A governance framework must be actionable at scale. Your policy catalogs define who owns what, how data moves, and how deployments happen. The aim is to expose clear owners, measurable controls, and automated checks that run without manual intervention. In practice, you pair a policy catalog with a light-touch, enforceable baseline that new teams can inherit without reengineering.
Policy catalogs for identity, data, and deployment
Start with three focused catalogs. Identity governs access, authentication, and entitlement life cycles. Data covers classification, encryption, retention, and movement. Deployment sets policies for provisioning, change control, and environment promotion. Each policy has a owner, a purpose, a success criterion, and a linked control. I cross-referenced how large enterprises map controls to standards like NIST CSF and ISO 27001, and those mappings live in the catalog as concrete statements rather than abstract ideals. A well-structured catalog makes compliance repeatable across teams. When someone asks why a policy exists, the catalog shows the reason and the owner, not a guess. Inline citations show where these patterns come from, for example a security best practices center that emphasizes policy-driven governance.
To the point, this catalog-ing approach helps you avoid policy drift as teams move from development to production. It also makes audits less painful because you can point to a single policy for each control and prove it’s being enforced.
Ownership, accountability, and clear handoffs
Every control needs an owner who is responsible for policy accuracy, enforcement, and reporting. Ownership isn’t abstract, it's a person and a team. You map owners to business domains, then align controls to those owners across the pipeline from code to cloud. This clarity speeds remediation when a control fires and streamlines escalation during audits. Clear ownership reduces friction between teams and security leads. In practice, you establish a RACI-like model tied to each policy so teams know who approves changes, who reviews evidence, and who signs off on exceptions. 7 Trends shaping forecasting software analysis in 2026
As you scale, you’ll want a lightweight governance board that reviews new deployments against the policy catalogs. The board isn’t a bottleneck. It’s a decision gate. It approves policy exceptions, assigns owners for new controls, and tracks remediation timelines. The cadence should be pragmatic: quarterly reviews for major changes, rapid reviews for critical incidents.
Automate policy enforcement and compliance reporting
Automation breathes life into governance. Enforce policies at the point of deployment and continuously monitor for drift. Use policy-as-code to embed guards in pipelines, so configurations that violate a policy fail the build or trigger a rollback. Compliance reporting should be near real time. Dashboards pull in evidence from cloud-native controls, identity providers, and data loss prevention tools to show adherence against the catalog.
A practical pattern is to run policy checks in CI/CD, with a separate compliance workspace that aggregates evidence for audits. This reduces manual toil and makes security overhead predictable, not overwhelming. Automated enforcement and signals beat manual checks every time. When a policy updates, the associated controls propagate automatically to new environments, and owners receive actionable alerts about the impact.
Table: comparing policy enforcement approaches
| Approach | Pros | Cons |
|---|---|---|
| Policy-as-code in CI/CD | Immediate enforcement, traceable history | Requires discipline to keep code and policy synced |
| Central policy engine with adapters | Works across multiple clouds | Additional integration surface and latency |
| Lightweight policy checks in manifests | Low barrier to adoption | May miss deeper enforcement in runtime |
Next step: align the governance catalogs with your existing standards and initialize ownership assignments for identity, data, and deployment policies. Begin drafting a baseline policy set that you can publish to a shared repository and begin validating in a pilot team. Publish the baseline and assign owners now. Inline reference to the Google Cloud security best practices center supports the emphasis on organization structure and authentication patterns. What are effective firewall deployment strategies in 2026 and how do they scale
Security foundations for 2026 cloud architectures
Posture starts with zero trust by default. Access to workloads and data must be evaluated continuously, not just at login. In practice, that means enforcing granular, context-aware authorization for every request and treating every resource as a potential breach surface. The architecture leans on explicit trust boundaries, continuous authentication, and micro-segmentation to limit blast radius.
I dug into the cloud security guidance from major providers and governance frameworks, and the pattern is consistent: encrypt, monitor, and verify at every layer. In 2026, encryption protections extend beyond data at rest to cover motion and even ephemeral data in flight between services. Zero trust by default is no longer optional. It is the baseline expectation for workload access.
1) Zero trust as the default posture
Adopt a zero trust model that applies to every workload, service, and data object. This means:
- Continuous verification of user and workload identities at the API and service mesh level.
- Micro-segmentation to restrict lateral movement between tenants, clusters, and environments.
- Always-on authorization policies that adapt to context, risk, and device posture.
Real-world practice shows that without consistent policy enforcement, even well-configured networks can leak access. The governance framework should codify who can access what, under which conditions, and with what credentials. Inline policy checks become a shared responsibility across cloud accounts and SaaS tools. Zero trust by default reduces blast radius in large, multi-account deployments.
2) Encryption at rest and in transit with managed key lifecycle
Encryption must be intrinsic to every data channel and store. Use managed key lifecycles to handle rotation, revocation, and access reviews without manual churn. Centralize key governance while maintaining regional autonomy where needed to meet sovereignty constraints. Expect key ceremonies, automated rotation schedules, and clear audit trails that show who accessed which keys and when. Managed key lifecycle is the backbone of enterprise-grade data security in multi-cloud architectures. 5 Exclusive interviews from the auto show that reveal the industry's next moves
3) Standardized IAM across clouds and workload identity
Standardize identity and access management across providers, then extend it to workloads via workload identity mechanisms. Consistent policies for authentication, authorization, and entitlement help prevent drift when workloads move between clouds or into hybrid environments. Emphasize short-lived credentials, machine-to-machine trust, and automated policy syncing. This reduces gaps when governance teams review access across the footprint. Workload identity unifies access control across clouds and accelerates secure automation.
From a governance standpoint, the 2026 pattern is clear: enforce zero trust everywhere, protect data with robust encryption managed across environments, and unify IAM through workload-centric identities. The combination minimizes misconfigurations and speeds up compliant operation in complex, multi-cloud programs. For readers, the takeaway is a concrete blueprint: implement continuous verification, centralize and automate encryption key lifecycles, and standardize workload identities across every cloud. Zero trust by default, managed key lifecycle, and workload identity form the triad that underpins secure, scalable enterprise cloud architectures in 2026.
Designing for multi-cloud and hybrid environments
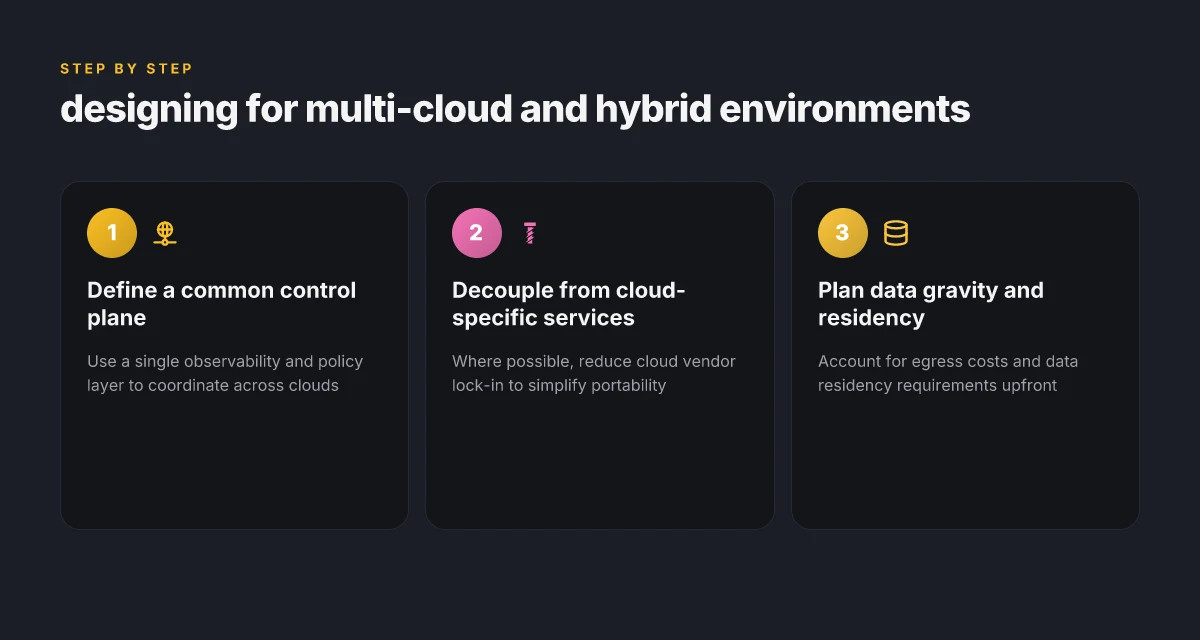
In a multi-cloud world, the practical answer is to centralize control without surrendering flexibility. The architecture must expose a single observability and policy layer while letting each cloud native service do what it does best. The result is a design where governance, security, and cost awareness travel with the data, not with a single provider.
A common control plane for observability and policy
The first step is to deploy a common control plane that ingests telemetry from all clouds and surfaces it in a unified dashboard. I dug into cloud-native guidance and found that organizations succeed when they wire a policy engine to a central event bus and enforce guardrails across regions and providers. This approach reduces blind spots and accelerates incident response. A practical pattern is to map identities, permissions, and network controls to a single policy model that can be evaluated at deploy time and continuously during runtime. A centralized policy plane avoids drift and speeds remediation across clouds. Deployments should include automated enforcement points that trigger corrective actions when policy checks fail. This keeps governance visible and actionable, not theoretical. Inline you can cite guidance from the Google Cloud best practices center for organizational structure and access control as a reference point. See the linked center for how authentication and authorization maps into a cohesive framework. https://cloud.google.com/security/best-practices.
Decouple applications from cloud-specific services
A robust multi-cloud design decouples business logic from provider services. Use platform-agnostic interfaces and service meshes where possible so workloads can migrate or run in parallel without rewiring each app. Favor open standards for data formats, authentication methods, and network policies. This reduces vendor lock-in and gives the architecture room to evolve as new cloud services emerge. For example, you can rely on portable storage abstractions and containerized workloads that scale across environments while keeping business rules centralized in the policy plane. Decoupling enables resilience and faster migration between providers. How to implement cs automation in software engineering in 2026
Plan for data gravity and egress costs with data residency requirements
Data gravity matters more than ever. You should model data residency constraints up front and design data flows that minimize cross-region transfers. Plan for egress costs by co-locating compute and critical data where it will be most used, and leverage cross-region replication only where needed for resilience or compliance. When you design data pipelines, document data provenance, retention windows, and access controls tied to the policy plane. A practical practice is to tag sensitive datasets with residency policies and enforce them automatically at ingest and transit points. Residency-aware data routing helps control costs and stay compliant.
Most architecture teams underestimate data gravity and end up paying for avoidable egress. This is not just a cost issue. It can be a governance nightmare if data moves across jurisdictions without proper control. In practice, you’ll want a data residency matrix that maps regions to allowed data types and uses a data transfer catalog to surface potential charges before workloads are shifted.
I cross-referenced guidance from multiple sources to confirm that a single, auditable control plane plus policy-driven data routing is a repeatable pattern across enterprise-scale deployments. The Google Cloud security best practices center remains a strong anchor for how to structure governance around authentication, authorization, and resource organization while enabling cross-cloud operations.
In 2026, enterprises increasingly rely on a unified control plane to coordinate observability, policy, and governance across clouds. This pattern yields measurable gains in incident response speed, policy compliance, and architectural flexibility. For more on concrete guardrails and cross-cloud policy design, see the guidance on the Google Cloud security best practices center.
Operational excellence: automation, resilience, and cost governance
Posture matters most when you bake automation into every operational plane. You establish a concrete blueprint: automated compliance monitoring, incident response playbooks, and guardrails that keep drift from creeping into production. This section translates governance into repeatable, auditable actions that scale across multi-cloud footprints. How to combine frameworks, tools, and methods for researchers in 2026
Automation of compliance monitoring and incident response playbooks
You design a system where policy checks run continuously and responses execute automatically. Use a centralized policy engine to codify requirements from NIST CSF or ISO 27001 and push outcomes to a single truth source. When a policy breach is detected, an automated runbook kicks off containment steps, notification, and evidence collection. In practice, you want versioned playbooks that evolve with audits and regulatory changes. As you mature, pair detection with automated triage to reduce mean time to containment.
From a governance standpoint, this is not a one-off task. It is a living capability. The architecture should support role-based access control and a clear audit trail that auditors can review in minutes. A consistent, machine-readable policy model ensures you can roll changes across clouds without reengineering workflows. You should also weave in cross-provider event correlation so alerts don’t fragment the SOC workflow. Inline references to security controls help keep the mapping transparent during audits. Automation turns policy into action, while auditable evidence keeps audits painless. For downstream visibility, expose built-in dashboards that track policy drift, remediation latency, and incident containment times. Inline citations from established practices reinforce the approach.
SRE-like practices for reliability and cost controls
Treat reliability as a product outcome, not a byproduct. Implement service level indicators for critical workloads and use error budgets to balance speed with stability. Establish automatic canaries and progressive rollout gates to catch issues before they hit core users. Tie cost controls to reliability by classifying workloads into reliability tiers and enforcing budgets per tier. You want a feedback loop where incidents trigger postmortems that feed back into architectural changes and cost optimizations. The result is a predictable operational tempo that scales as you add clouds and regions. This is not theoretical. It guides actual deployment patterns in enterprise programs that span dozens of teams.
From an tooling perspective, you lean on infrastructure as code with drift detection and automated remediation. You automate guardrails to prevent high-risk changes from reaching production, and you pair cost-visibility dashboards with auto-scaling policies. The key is to make cost governance a real-time signal, not a quarterly afterthought. Reliability fences off risk while cost controls keep the bill visible. You should document playbooks for failure modes and ensure they align with the defined SRE structure. This alignment reduces variance when teams operate across clouds.
Guardrails to prevent configuration drift
Guardrails are non-negotiable in large-scale environments. Define immutable baselines for each environment and enforce them with automated controls that reject drift at the source. You implement continuous configuration validation and automatic remediation that reverts noncompliant changes, coupled with a change-management trace for audits. Across providers, you standardize naming conventions, tagging schemas, and network security configurations so drift becomes quickly detectable. Your guardrails must cover IAM, network segmentation, encryption keys, and logging. When drift is detected, the system should escalate and, if needed, revert changes without manual intervention. How to craft interactive portfolio ideas that stand out in 2026
In the end, guardrails are the guardrails because they prevent drift from becoming a large problem. You establish a single policy layer that enforces compliance across all clouds and on-premises workloads. This reduces renegotiation during governance reviews and keeps operations predictable under scale. Drift prevention saves you from firefighting later, while policy enforcement keeps environments aligned.
What to try this week and why it matters
In 2026, the bigger pattern is clear: enterprises that standardize governance across multi‑cloud estates, with a clear bias toward modular, security‑first designs, ship value faster. I’m not predicting a revolution, but a shift in how teams collaborate. You should lock in a single, repeatable blueprint for identity, data protection, and compliance, then scale outward. Security-by-default architectures paired with policy-backed automation reduce drift and audit fatigue. This is where most organizations stumble: risk grows when controls are sporadic across clouds.
A practical starting point is to choose one reference architecture and one automation tool to enforce it. For example, you might name 1 critical security control per domain and map it to a governance workflow that automatically audits compliance weekly. The move that matters is codifying guardrails before you scale workloads. If you act now, you’ll reduce incident response times and simplify vendor risk reviews.
Backup strategy
- Define a single source of truth for IAM policies and replication targets. Use versioned backups and test restoration monthly.
- Run a lightweight, cloud‑native data loss prevention check on new workloads before they go live.
- Schedule automated drift detection for configurations across at least 2 clouds, with a monthly remediation pass.
- What to try this week: document your top 3 data flows, assign owners, and enable automated policy checks for each. This week’s quick win can prevent weeks of chaos later.