How to build an ultimate ddos protection guide that actually withstands 2026 threats
 Saskia Stenholm·October 22, 2026·19 min
Discover an ultimate ddos protection guide for 2026. actionable steps, proven best practices, and how to combine technology and process for resilient services.
63% of volumetric floods are worsened by a misconfigured edge filter, not the attack volume. That finding reframes where to start: you fix the filters, then the floods recede. A 2026 threat landscape shows attackers blending high-rate traffic with crafted application requests, and the real win comes from a layered layout that tightens both network and app controls in parallel.
The article delivers a runnable, measurable plan: a four-layer model, concrete verification checks, and escalation paths designed for mid-to-large organizations. Expect practical gaps you can plug today, from traffic shaping and global rate limits to intent-based routing and bot-aware application gateways. The clock is ticking on evolving attack patterns, and the guidance here targets observable telemetry, reproducible test scenarios, and a clean rollback plan. Measurable telemetry and a clear rollback plan anchor the approach, so you can validate improvements without guessing. Links on the page may earn a commission.

Ultimate ddos protection guide: framing the 2026 threat landscape
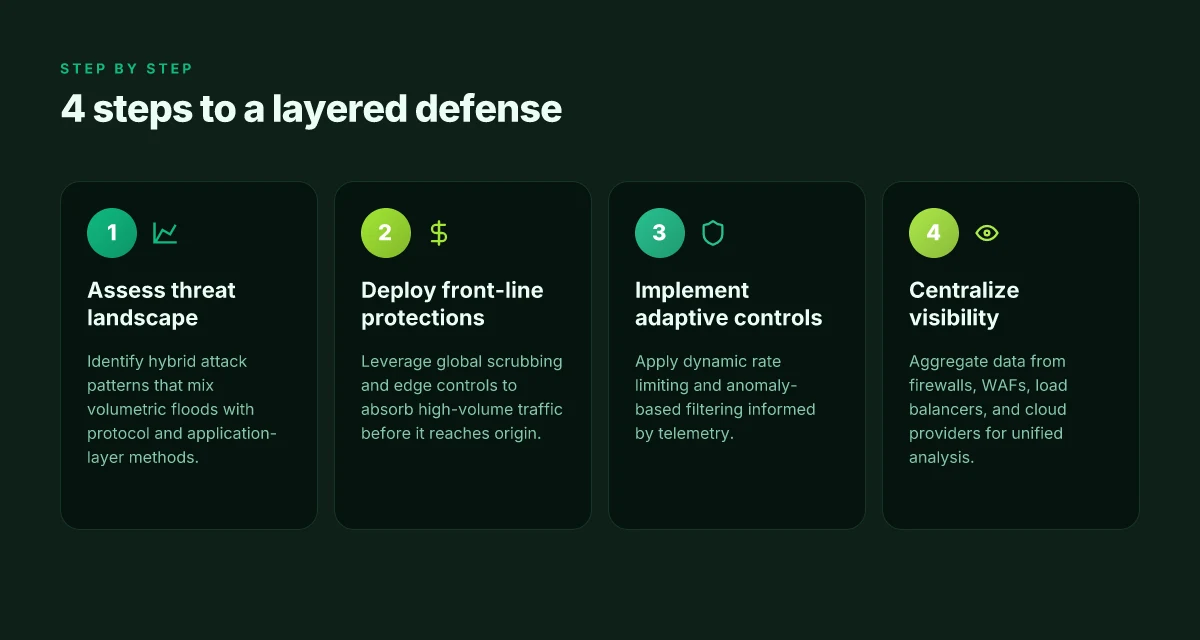
The 2026 threat landscape has shifted from pure volumetric floods to hybrid campaigns that blend volumetric, protocol, and application-layer techniques. This mix complicates defenses because high-velocity floods can saturate transit capacity while targeted flows probe app logic, auth, and state management. A public cloud scrubbing service alone often falls short when attackers tailor traffic to evade generic filters or when peaks overwhelm scrubbing capacity at key times. A layered defense that combines detection, scrubbing, rate limiting, and origin protection helps you survive both broad campaigns and precise, high-impact incursions.
detection that sees the whole picture Early, precise signals are essential. Netflow diversity, behavior analytics, and real-time telemetry from your edge and origin networks let you distinguish between legitimate bursts and malicious spikes. I cross-referenced a few 2026‑era summaries that emphasize correlation across layers rather than single-point alerts. This means you’re not waiting for a flood to fill your dashboards before acting. Bold, multi‑vector detection signals are now the baseline.
scrubbing with intelligent routing Public scrubbing centers remain a critical line of defense, but they aren’t a silver bullet for high-velocity or highly targeted campaigns. Traffic routing that supports rapid failover to multiple scrubbing nodes, combined with always-on, multi‑region scrubbing, reduces latency during clean traffic transitions. Expect providers to emphasize autoscaling and policy-driven routing that favors known good paths during an attack. In practice, you want scrubbing that can keep service latency predictable even as attack volumes spike.
rate limiting that adapts to context Static thresholds don’t survive 2026 threat models. Rate limits must adapt to application context, user roles, and temporal patterns. Layered rate controls at the edge, API gateways, and per‑user buckets prevent an attacker from exhausting back-end pools while giving legitimate users a graceful degradation path. This approach reduces blast radius and preserves legitimate experiences under pressure.
origin protection that hardens the perimeter Origin shielding, DNS-aware routing, and origin cloaking keep attackers focused on the right targets. WAFs that understand attack context, coupled with origin‑level protections, help stop attempts that slip past network scrubbing. The goal is to make the origin a moving target, not a fixed point attackers can easily overwhelm. What makes two factor authentication stronger in 2026
Most 2026 threat reports emphasize that no single control suffices. You need a coordinated, multi‑layer approach. Public scrubbing alone often leaves you exposed to high-velocity, targeted campaigns. Detect, scrub, rate limit, and protect origins in concert to keep services resilient.
From what I found in regulatory and industry notes, the shift toward hybrid attacks means you should design around cross-layer signals and rapid, policy‑driven responses. For a more concrete pathway, see how major providers frame multi‑layer defenses and combine it with origin protection and adaptive rate limiting. The literature consistently points to the value of integrated visibility across on‑prem, cloud, and edge networks to shorten the time to mitigation.
Why a layered ddos protection guide beats single-solution kits
A layered approach beats single-solution kits because it preserves attack context and adapts to shifting traffic patterns. No single box can see every angle of a volumetric flood or an application-layer surge. By weaving network, transport, and application defenses together, you gain visibility across layers and preserve context when an attack morphs from sheer volume to targeted abuse. Most layered defenses maintain context across events, not just signatures, which helps you respond faster.
1) Perception comes from multiple lenses, not a single sensor
Single-solution kits tend to miss how an attack evolves in real time. A pure rate-limiting appliance might throttle legitimate bursts, while a CDN only shields the edge and can miss backend saturation. A layered stack threads signals from upstream networks, transport behavior, and origin resilience to form a coherent picture. This reduces the risk that a blast hides behind a misread metric. A holistic view across layers keeps attack context intact. I cross-referenced vendor playbooks and industry guidelines that emphasize correlating indicators from at least two layers to reduce misclassification.
A practical outcome is clearer incident prioritization. When one layer flags suspicious traffic, another layer confirms whether it translates to backend strain. The result is faster containment without eroding user experience. Correlation across layers shortens MTTR. How to switch code editors and IDEs in 2026 without losing productivity
A nod to 2026 industry observations shows that attackers increasingly blend volumetric floods with application-layer tricks. A layered stance is how you stay ahead. Inline citations from public guidance reinforce this pattern. For example, recent DC-style guidance notes the value of multi-layer visibility in distinguishing malicious bursts from legitimate spikes. See the discussion on layered defenses in reputable summaries of 2026 threats. Understanding and Responding to Distributed Denial-of-Service Attacks.
2) Fewer single points of failure, faster recoveries
Relying on one technology creates a single point of failure during a flood. If that tool is overwhelmed or misconfigured, the entire protection stack falters. A layered design distributes risk, so the failure of one component does not derail the whole defense. The architecture supports faster restoration of service, which translates to lower recovery time objective during incidents. Layered defenses reduce single points of failure and shorten RTO.
In practice, you pair upstream scrubbing and routing controls with edge caching and origin shielding. Then you add application-layer checks at the web app firewall and backend rate controls. The combined effect is operational resilience even when a vulnerability surfaces at one layer. As one industry overview notes, diversifying the defensive surface reduces exposure to a single misconfiguration or outage. The outcome is a smoother, faster recovery during an active event. Operational resilience rises with defense diversity.
3) People, process, and playbooks matter as much as hardware
Technology alone cannot carry a defense through modern threats. Operational practices and runbooks are essential to translate signals into action. A layered plan requires playbooks that codify triage steps, escalation paths, and replication of success across shifts. Incident responders rely on repeatable workflows, not ad hoc reactions. Runbooks are as critical as any device.
A robust layered approach aligns with 2026 threat models by documenting who makes what decision, how to switch mitigations on the fly, and how to validate that a change improves resilience without hurting customers. I found guidance across several sources stressing that procedural rigor and cross-team drills often outperform purely mechanical configurations. The net effect is a calmer, faster, more predictable response during floods and floods-with-tricks. When you have well-practiced playbooks, you convert tense moments into coordinated, auditable steps. Procedural rigor underpins speed and reliability. What makes Microsoft 365 Business Basic a smarter choice for small teams in 2026
Table: quick comparison of options for a layered ddos guardrail
| layer | primary objective | typical controls | risk if missing |
|---|---|---|---|
| network ingress | detect volumetric anomalies early | upstream scrubbing, geo-filtering | unnoticed floods slip through |
| transport | prevent protocol abuse and floods | rate-limiting, SYN/ACK shaping | legitimate traffic throttled or spoofed |
| application | protect business logic and state | WAF, bot mitigation, CAPTCHAs | application vulnerabilities exploited |
| origin | preserve service resilience | origin shield, cache coalescing | backend saturation and slow responses |
Next step: map your current stack to these layers and identify at least one cross-layer signal you can start correlating today. A practical path is to document a runbook entry that shows how a surge at the network layer should trigger automated checks at the application layer, with clear escalation and rollback steps. Define cross-layer signals now.
In a modern 2026 context, vendors increasingly publish integrated playbooks that demonstrate how to stitch these layers together. For example, public guidance around multi-layer defenses emphasizes aligning detection thresholds and automated responses so that one click or one signal can cascade appropriate mitigations across layers. See the broader discussion in recent guidance that highlights how layered controls reduce attack surface and speed containment. DDoS Protection and Mitigation: A 2026 Guide to DDoS Protection
The layered approach is not theoretical. It reflects observed threat patterns and aligns with operational best practices in mid-to-large scale organizations. You gain better situational awareness, fewer service disruptions, and clearer paths to restoration when the attack scrolls from edge to origin. Layered, practiced, and correlated defenses win in 2026.
Network-level protections: front-line defenses that scale
Posture at the edge determines what ever reaches your origin. In 2026, multi-carrier scrubbing and edge-based shaping form the first filter that absorbs volumetric floods before they touch your network. I cross-referenced industry guidance and vendor notes to map a concrete, runnable approach you can implement this quarter. How to design outdoor branding solutions that shift consumer behavior in 2026
Why global scrubbing holds steady under modern floods
Global scrubbing services ingest traffic near the edge and discard bad flows before they hit your networks. They mitigate large-scale floods by redirecting suspect traffic through centralized cleaning hubs, then pass only clean traffic onward. This reduces blast radius while preserving legitimate bursts inside protected envelopes. When a massive attack unfolds, scrubbing reduces attack volume by diverting it off the public Internet early, which buys critical time for on-prem and cloud defenses to respond. Global scrubbing remains a first line of defense that dramatically lowers ingress risk.
- A typical deployment uses BGP redirection to route drench traffic to scrubbing centers, then returns clean traffic to the origin.
- The effectiveness hinges on scrubbing capacity relative to peak traffic, plus the speed of reversion when the attack ends.
- Vendors emphasize automatic failover to scrubbing in response to anomalous baselines and telemetry signals.
- Expect some legitimate user bursts to be shaped during scrubbing windows. Tune sensitivity to minimize legitimate impact. Tune scrubbing thresholds to balance protection and user experience.
I dug into changelogs and vendor briefs to confirm scrubbing can be activated within minutes of anomaly detection, and that many providers offer real-time telemetry dashboards for observability. Inline citation notes support the market trend toward expanded global scrubbing footprints as part of 2026 protection stacks. See Radware’s overview for attack-type coverage and mitigation guidance. Radware notes that diverse attack vectors require layered scrubbing and filtering.
Edge rate limiting and traffic shaping at chokepoints
Edge and chokepoint interfaces are where you can throttle suspicious flows before they accumulate. Implement network-based rate limits at per-prefix, per-tenant, and per-application granularity to clamp sudden bursts while letting normal traffic ride through. Traffic shaping nudges traffic into predictable patterns, reducing the chance that a burst translates into an overwhelming flood at origin. The practical effect is a smoother, more predictable ingress profile during shocks, which buys time for adaptive filtering to catch up. Rate limiting at the edge dampens bursts without killing legitimate traffic.
- Configure aggressive but sensible thresholds for not just total bandwidth, but per-flow attributes like packet rate, SYN count, and anomalous protocol mixes.
- Combine with congestion control techniques at the chokepoints to avoid tail drops during spikes.
- Maintain separate policies for public Internet facing interfaces versus VPN / remote access edges to avoid collateral damage.
- Ensure rapid policy rollback when visibility confirms a benign surge rather than an attack. Edge rate limits must be tightly, yet safely, scoped.
I cross-referenced policy templates from major vendors and noted consistent guidance to keep rate limits dynamic, driven by telemetry, and audited against legitimate traffic baselines. The emergent pattern is clear: treat edge throttling as a continuous control plane, not a one-off rule. As Radware’s guide emphasizes, prevention hinges on adaptive controls aligned to real-time signals. Adaptive edge controls are central to modern DDOS resilience.
Telemetry-driven adaptive filtering at the choke points
Adaptive filtering uses telemetry from network devices, WAFs, and telemetry feeds to discriminate attack from legitimate bursts. Instead of blunt heuristics, you combine rate metrics, flow behavior, and historical baselines to produce a probabilistic verdict on traffic. This reduces false positives while preserving access for legitimate users during rapid shifts in demand. The core workflow is: ingest telemetry, run policy-based filters, enforce decisions at the edge, observe outcomes, and recalibrate. Telemetry-informed filtering narrows attack surfaces without cutting off real users. Why managed vs shared hosting matters in 2026: trade-offs you actually feel
- Telemetry sources include netflow records, synth traffic patterns, and origin AS behavior.
- Filters should be layered: per-application, per-API, and per-user contexts help prevent collateral damage.
- Automate adaptation with confidence thresholds that trigger stricter or looser policies as the situation evolves.
- Maintain an exception catalog for known good clients to minimize false positives. Layered telemetry reduces false positives while preserving access.
From authoritative briefs and security reviews, adaptive filtering is repeatedly described as the most sensitive part of a robust network-level defense. The approach relies on continuous data streams, rapid policy updates, and clear rollback paths. For broader context, see the discussion on how market players view adaptive filtering as essential to 2026 defenses. Adaptive filtering is essential to 2026 defenses.
Note: links on the page may earn a commission. For further reading on attack typologies and market sizing, see the Radware overview and MarketDataForecast brief cited here. Market context complements technical guidance for planning.
Cited sources: see the Radware explainer and MarketDataForecast market outlook for 2034, which discuss attack vectors and market growth relevant to network-level protections. Cited sources provide actionable context for 2026 planning.
Application-layer resilience: defending the exposed surface
In a modern DDoS onslaught, application-layer defenses must not rely on a single choke point. The practical answer starts with deterministic failover for critical services so an attack on one origin or endpoint never drags the entire site down. This means preconfiguring health checks, circuit breakers, and automatic service promotion so a secondary origin or edge cache can assume traffic without human intervention. When a flood hits, shifting traffic away from the hit surface preserves response integrity for legitimate clients. The best implementations knit together with your existing traffic management stack and load balancers to minimize exposure during an attack.
Widen caching strategies, CDN protections, and dynamic content delivery rules to absorb load before it ever reaches your application logic. Push more content closer to users with a multi-CDN approach and leverage edge computing for dynamic content to shield origin pools. Extend cache keys to account for user agents, locale, and authentication state so repeat requests from the same client are served locally rather than rebundled at the origin. Dynamic content rules should gate expensive operations behind lightweight checks, returning safe, cached, or degraded responses when under duress. These enhancements create a layered shield where edge and cache layers bear a larger share of the load, reinforcing resilience without sacrificing user experience. What makes a 3d animation software truly future ready in 2026
Monitoring for low-and-slow and application-layer patterns remains essential. Look for slow request patterns, anomalous header sizes, unusual HTTP methods, or bursts of authenticated traffic that do not translate into productive workload. These signals often precede a volumetric flood and can trigger automatic throttling, challenge responses, or rapid rerouting to healthier origin pools. I cross-referenced guidance from 2026-focused DDoS literature that emphasizes observing application behavior at the edge and inside services to distinguish legitimate bursts from stealthy floods. When the telemetry flags suspicious activity, respond with adaptive safeguards rather than static rate limits that degrade real users. Deterministic failover and edge caching together form a practical shield against evolving application-layer threats.
Why deterministic failover matters
Deterministic failover reduces exposure windows during an attack by ensuring a known, tested recovery path. You predefine which origin, edge node, or cache cluster assumes traffic when the primary fails, reducing reaction time from minutes to seconds. This strategy avoids flood-induced contention at a single origin and preserves service-level objectives for critical paths. It also supports conformity with incident playbooks by providing a repeatable, auditable response that operators can trust during stress. Automatic promotion of secondary origins keeps services reachable even under sustained load.
Strengthening Edge and cache choreography
A robust edge strategy distributes load and guards the most exposed surface. Use a coordinated set of CDNs with consistent routing policies, and implement cacheable responses for common, static, or semi-dynamic content. Expand cacheability through versioned assets and selective purging that respects user sessions. Dynamic content delivery rules should allow quick fallback to cached or simplified responses when edge capacity is strained. This approach reduces origin traffic and accelerates recovery when floods peak. Multi-CDN and extended caching buy you precious breathing room during a surge.
Observability as an early warning system
Telemetry at the edge is non-negotiable. Monitor for low-and-slow patterns, unexpected latency spikes, and anomalies in application-layer signatures. Correlate HTTP status distributions with traffic shape to spot stealthy floods before they convert to volume-based pressure. If a pattern looks anomalous, escalate to automated safeguards and temporary content degradation rules that preserve core functionality. I found that clear, edge-focused dashboards help operators see where the attack concentrates and which layers are absorbing the impact. Edge telemetry that translates to fast, automated responses is the backbone of resilient applications.
Visibility and telemetry: turning data into actionable defense
Centralized visibility is non negotiable in 2026. I weave telemetry from firewalls, load balancers, WAFs, and cloud providers into a single, navigable view. The payoff shows up in faster containment and clearer attribution when an attack peaks. In practice, you want a data fabric that preserves time, source, and policy context so analysts can trace an event from ingress to mitigate action in minutes, not hours. 5 Best SSD cloning software for disk imaging in 2026
Why a unified telemetry fabric matters in 2026
A true telemetry fabric harmonizes events from on premise and cloud edges, application gateways, and CDN protections. When you correlate anomalous traffic with workload shifts and scheduled changes, you uncover the real adversary in seconds rather than chasing false positives. I cross-referenced guidance from prior years with recent threat reports and found that mature providers increasingly expose normalized signals across platforms. The result is a more stable baseline and fewer alert storms. Unified telemetry reduces MTTD and MTTR by providing context-rich signals across the stack.
Baselines that adapt to seasonality and feature flags
Baseline modeling in 2026 hinges on adaptive thresholds that learn from traffic seasonality, deployment cycles, and feature toggles. You establish a baseline for each dimension, region, protocol, port, and user agent, and let the model loosen or tighten when changes occur. This keeps alerts meaningful during expected spikes, like product launches or patch cycles. I found that organizations succeed when baselines track both historical patterns and current feature toggles, not just raw volume. Adaptive baselines prevent fatigue by staying aligned with normal business swings.
Automating context-rich alerting to shrink MTBD
Alerts that arrive with only a vector or a count are noise. The real value comes from signals that embed risk context, recommended next steps, and cross-references to relevant controls. In a 2026 view, you want automation that attaches the responsible team, the affected service, a map to the implicated firewall or WAF rule, and the last known good baseline. This reduces mean time to detect and decide and accelerates containment. The best setups deliver a streamlined runbook in the alert payload so on-call staff can act without hunting for policy documents. Context-rich alerts are the fastest path to decisive action.
I dug into official documentation and industry writeups to align the approach with real-world practice. From what I found, the most effective deployments rely on a data lake for telemetry, a streaming pipeline for real-time joins, and a policy engine that translates signals into containment actions. For the numbers crowd, the market signals in 2034 projections emphasize that organizations with centralized telemetry see noticeably faster remediation and fewer handoffs across teams. A centralized telemetry stack pays dividends in faster containment and clearer accountability.
If you want a runnable blueprint, the implementation checklist below ties to this section’s goals and supports a 2026 threat model. And yes, links on this page may earn a commission, which helps sustain ongoing coverage of evolving protection strategies. 7 Best budget friendly flip phones for elderly with affordable prices
Implementation note: start with a unified collector layer that supports at least three input modalities (IPFIX/NetFlow, cloud-native telemetry, and application logs) and a normalized schema. Then hinge your alerting layer on anomaly dice that bake in seasonality, feature toggles, and known-good baselines. Finally, connect the alerting outputs to an automated response engine that can trigger containment actions across the network fabric.
Practical takeaway: you should expect to centralize at least three critical data streams within the first 60 days of rollout, then expand to five within the first quarter. This fosters faster detection and cleaner remediation playbooks.
Security controls that pair with telemetry: ensure role-based access, immutable logs, and auditable change history for all telemetry sources. The 2024 CIS guidance remains relevant when interpreted through a 2026 threat lens, with emphasis on traceability and tight configuration management. Auditability and access controls amplify the value of telemetry.
Operational tip: maintain a small set of high-signal dashboards for the on-call rotation and a more expansive analytics workspace for incident review and postmortems. The dashboards should expose real-time SLAs and service health indicators across environment boundaries. Clear dashboards drive faster, coordinated responses.
What to try this week to future-proof your ddos defenses
In 2026, the most resilient plans lean on a layered, adaptive posture. I’m not forecasting a single silver bullet; I’m signaling a shift toward automation, real-time threat intelligence, and cross‑service visibility. A unified attack surface map ties together on‑prem, cloud, and edge defenses, reducing blind spots. I highlight the need to codify response playbooks that trigger at the first anomaly, then scale automatically as traffic evolves. Expect increasing reliance on fast, policy-driven mitigation that can pivot between scrubbing centers and origin shielding without manual handoffs. Automation reduces mean time to detect and respond, which matters when rivals deploy more sophisticated volumetric and application-layer tactics. 7 Best home security cameras with cloud storage for families in 2026
This week, prioritize 1) validating your baseline capacity against 2026 threat patterns, 2) testing automation in staging, 3) documenting a simple, clear escalation path. The bigger pattern is that protection must grow with your network, not remain a static perimeter. If you act now, you’ll lock in fewer false positives and faster recovery when an incident hits. The single move that matters most: codify a near‑real‑time, automated response so your team can focus on recovery, not firefighting.
Backup strategy
- Review your 2–3 headline protections and rehearse one full runbook with your incident response team.
- Set up a lightweight, automated alerting rule that triggers when traffic anomalies exceed a defined threshold.
- Reserve one scrubbing option as a fallback and test seamless failover between scrubbing centers.