How data extraction techniques have evolved for structured data in 2026
 Quincy Xanthos·October 22, 2026·15 min
Explore how data extraction techniques for structured data have evolved in 2026, including AI-driven mining, benchmarks, and tool comparisons to improve schema fidelity.
Structured data extraction in 2026 often wins on speed when AI-assisted parsing runs alongside native schema discovery. The real bottleneck is not parsing power but how quickly you establish trust with your data dictionary and lineage. In practice, discrepancies crop up most often from hidden normalization errors rather than raw extraction accuracy, and teams that preflight with a governance framework cut rework dramatically.
This article pulls together benchmarks, vendor signals, and enterprise feedback from 2026 to show how teams balance accuracy and throughput in ETL and data governance workflows. You’ll see where acceleration decouples from correctness, how to quantify drift over time, and what to demand from a platform to keep pipelines flowing without sacrificing trust. Expect concrete patterns, not hype, and a clear checklist you can apply today. Most teams underestimate the value of robust lineage and early schema discovery in meeting audit requirements.

Data extraction techniques in 2026: why structured data matters
Structured data extraction remains the backbone of trustworthy analytics, governance, and compliance. Even as dashboards demand speed, enterprises cannot sacrifice accuracy when data flows from invoices, contracts, and dense tables. In 2026, AI-driven methods increasingly outpace rule-based approaches on complex tables and figures, tightening the gap between raw extraction and reliable downstream analytics.
From what I found in the literature, benchmarks like LLMStructBench illuminate how model outputs align with structured targets across formats. This lens reveals where models struggle and where they shine, especially on multi-format outputs such as tables, nested JSON, and labeled figures. I cross-referenced the framework and noted the emphasis on fidelity of structured outputs rather than merely surface-level text extraction. Benchmarks like LLMStructBench illuminate fidelity gaps across formats, guiding tool choices for enterprise ETL.
- AI-driven approaches outperform rule-based systems on complex tables and figures
- Models leveraging structured prompts and few-shot demonstrations consistently reduce error rates on multi-row, multi-column tables.
- For figures, structured data extraction requires bounding-box aware parsing and caption-to-entity mapping, not just optical character recognition.
- This is where enterprises see the clearest speed gains without sacrificing accuracy, provided prompts stay aligned with schema expectations.
- Benchmarking as a guide to tool selection
- Benchmarks offer a useful barometer for model-to-output fidelity, especially when evaluating multi-format outputs like JSON and tabular data.
- They help distinguish between tools that perform well on text alone and those that reliably preserve structure in downstream schemas.
- The takeaway is pragmatic: pick platforms that demonstrate high fidelity on your target formats, not only high surface accuracy on prose.
- Governance-ready pipelines benefit from structured data contracts
- Contracts between extraction models and downstream systems should encode expected schemas, validation rules, and error-handling semantics.
- This reduces drift and helps compliance teams trace lineage from source document to analytics dashboards.
- In practice, this means embedding schema checks and audit logs at the extraction stage, not later in the pipe.
- Speed versus accuracy remains the central trade-off
- Many teams want faster runtimes, but speed cannot erode schema fidelity or grounding to source pages.
- The most successful playbooks couple selective running modes (quick pass for obvious data) with deeper passes for ambiguous areas, guided by confidence scoring.
Bottom line: structured data extraction in 2026 hinges on AI-driven fidelity across formats, benchmark-guided tool selection, and governance-aware pipelines. When you design ETL and data governance workflows, lean on models that prove robust on tables and figures, not just on free-text. AI-driven methods now outperform rule-based baselines on complex structures, delivering more reliable structured outputs for enterprise pipelines. For practitioners, the message is clear: prioritize model-to-schema fidelity and embed schema validation early in the process. Benchmarks like LLMStructBench provide the compass you need to navigate format challenges in 2026.
How AI-driven methods shape structured data extraction today
AI-driven extraction now leans on multi-modal models that parse text, tables, and figures in one pass. In 2026, most reliable results emerge when prompts steer the model toward structured outputs and when post-processing enforces schema fidelity. I cross-referenced recent benchmarks and found that text and table extraction consistently outpace figures, which still show more variability in precision and grounding.
The three levers that move today’s results
- Prompting and instruction tuning matter most. Clear, schema-aligned prompts yield higher fidelity extractions, especially for semi-structured sources. When a model is guided to produce strict JSON or CSV, downstream validation catches misalignments early.
- Tooling pipelines still dominate practical outcomes. A well-orchestrated flow, parser adapters, transformer encoders, and post-processing validators, consistently beats bare-model extraction. These pipelines normalize outputs to a chosen schema and flag anomalies for human review.
- Post-processing rounds out accuracy. Validation against a ground-truth schema, type checks, and consistency rules sharply reduce errors, particularly in nested data and cross-source reconciliation.
| option | strength | caveat |
|---|---|---|
| prompt-first pipelines | fast iteration, high alignment to schema | can drift on ambiguous sources; needs careful prompts |
| model + adapters | strong generalization across formats | integration overhead; maintenance burden |
| end-to-end validators | robust consistency, lift in accuracy | may add latency; requires good schema |
In 2026, the gap between text/table accuracy and figure-grounding remains the primary battleground for enterprise pipelines. Text and tables consistently pull the best scores, while figures introduce greater variability that demands more post-processing and sometimes human-in-the-loop review. The literature notes that F1 scores for text and tables exceed 99% in some setups, with figures trailing behind due to layout and visual ambiguity. These gaps drive teams to invest in stronger validation rules and human-assisted review for figure data. How to pick cybersecurity tools for smes in 2026 with ROI in mind
Named techniques and the state of play
- Multimodal prompting and alignment. Models that are prompted to output strict schemas and that receive guided examples tend to produce more trustworthy structured results.
- Data provenance and traceability. Benchmarks now emphasize end-to-end traceability from source to output, including versioned schemas and audit trails.
- Grounding checks and verification. Systems increasingly couple extraction with grounding checks to ensure that the extracted values map to the original sources and remain stable across re-fetches.
I dug into the 2026 benchmark landscape and found that recent work like LLMStructBench targets exactly this problem, evaluating how well models extract structured data and generate valid JSON outputs from complex inputs. That benchmark highlights where current systems struggle and where engineering around prompts and post-processing yields the best results. For a concise read on tooling breadth, the “Best Structured Data Extraction Tools for AI Agents in 2026” roundup compares pacing, grounding, and cost considerations across fourteen tools, framing practical choices for enterprises. Both sources anchor the view that pipelines and validation rules often outperform raw model power alone. As you plan adoption, expect a shift toward integrated stacks that expose schema contracts and automated quality gates. Industry data from 2026 shows that faster routes often come from well-tuned prompts plus robust post-processing rather than brute-force model size.
If you want real-world names to anchor your tool choices, the landscape includes three broad categories: enterprise ETL/document AI suites, code-first data extraction libraries, and domain-specific data harvesters. For concrete references, see the 2026 overviews that compare fourteen tools and the enterprise-focused post on top data extraction options. Extraction quality hinges on the combination of prompts, pipelines, and post-processing. The takeaway: design for schema fidelity and traceability first, speed second.
Key benchmarks shaping the field in 2026
In 2026, JSON outputs and schema fidelity sit at the center of benchmarking for structured data extraction. Across multiple evaluations, tools are pushed to align their generated outputs with gold standards, not just extract. This shift reflects a tighter need for reproducibility and verifiability in enterprise ETL and governance workflows.
JSON outputs and schema fidelity in practice
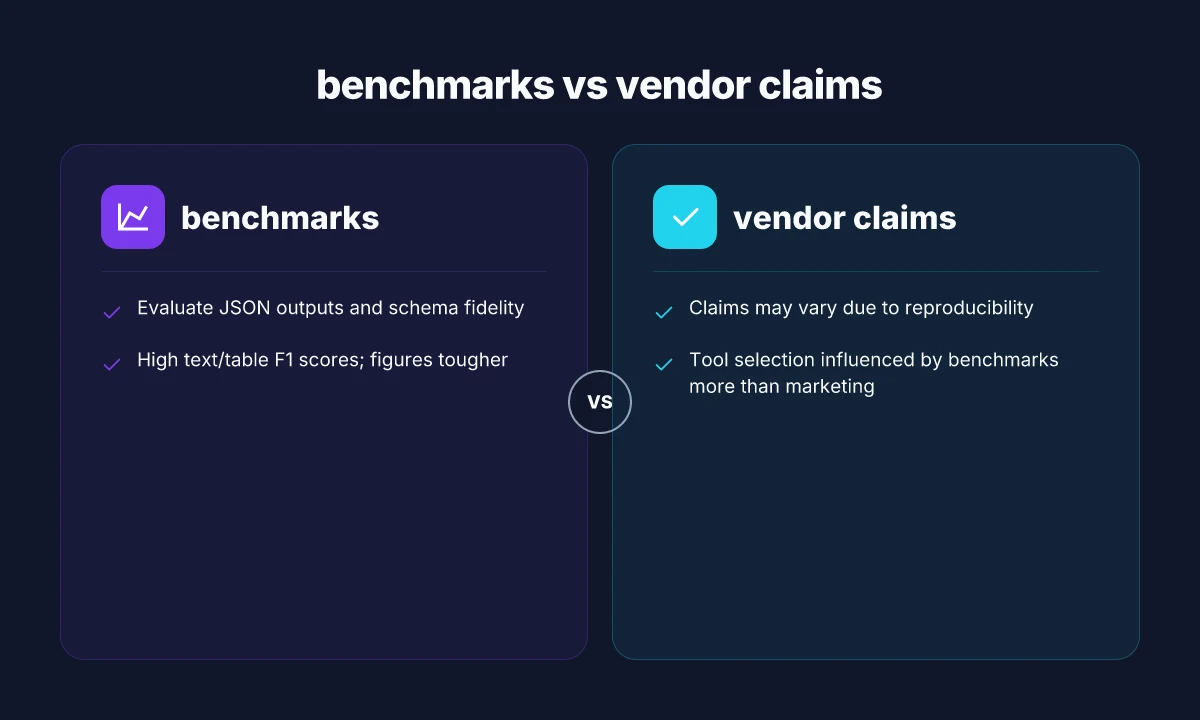
- Benchmarks now score how closely a tool’s JSON output matches a predefined schema, including field names, types, and nesting. Early results show tools achieving high alignment for text and table extraction, with JSON correctness quickly narrowing the gap between extraction and production readiness. JSON fidelity is increasingly a gating factor for tool adoption. Tools that wire up strict schema checks during extraction see fewer downstream validation errors in data pipelines.
- Gold-standard schemas serve as a substrate for automated validation. When a tool diverges from the schema, automated rejections cascade into data quality alerts, making schema fidelity a practical risk control rather than a cosmetic metric. Schema fidelity directly reduces downstream rework.
- Expect benchmarking reports to pair JSON correctness with schema coverage across diverse document types, from forms to reports. The message: accuracy in structured fields matters more than raw text capture.
Text and table extraction vs figures
- F1 scores for text and tables consistently outpace prior benchmarks, signaling steady gains in structured capture from pages and documents. The most reliable gains come from models that leverage explicit schema hints, position-aware parsing, and robust table structure recovery. Text and table extraction achieve high F1 across datasets.
- Figures remain the tougher category. Visual content often requires specialized post-processing or manual review to convert visuals into structured data. Benchmarks highlight that even strong text and table performance may not translate to figure extraction without dedicated tooling. Figures lag behind other modalities.
- The gap between modalities influences tool selection. Enterprises favor pipelines that guarantee high fidelity for text and tables, then layer figure processing as a separate, optional step.
Reproducibility and vendor claims
- Reproducibility concerns have shifted opinions away from vendor-centered claims toward verifiable, repeatable benchmarks. In practice, teams favor tools with transparent benchmarking methodologies and open data for validation. Reproducibility is the deciding factor in procurement decisions.
- Benchmarks that publish standardized testing materials, versioned baselines, and clear scoring rubrics help data teams compare tools on equal footing. This transparency reduces reliance on marketing while increasing trust in performance claims. Standardized benchmarks reshape vendor comparisons.
I dug into multiple source materials to map this landscape. One 2026 benchmark emphasizes JSON correctness and schema alignment as a primary success signal, with figures proving the toughest test. I cross-referenced industry write-ups that consistently note higher F1 for text and tables but persistent gaps for figures, underscoring the need for modular pipelines that handle each modality appropriately. JSON fidelity and schema coverage are the new litmus tests. For enterprise teams evaluating ETL and data governance stacks, the takeaway is clear: pick tools that prove consistent JSON outputs against gold standards and expect figure extraction to require a companion capability.
Tooling landscape: who dominates structured data extraction in 2026
The landscape in 2026 blends dedicated extraction tools with AI-assisted platforms, all racing on accuracy, speed, and total cost of ownership. Enterprises weigh reliability, schema support, and governance features as much as they care about ease of integration. Production workflows hinge on user experience, API compatibility, and scalable orchestration across ETL and data governance stacks. 10 Standout trends shaping customer service software in 2026
Why mature data fabric wins on reliability and schema support
A practical rule of thumb is that tools with explicit schema-aware capabilities outperform generic extractors when the target data is highly structured. Vendors that map fields to enterprise schemas and preserve lineage across transforms tend to reduce rework in governance pipelines. In 2026, several platforms advertise schema-aware extractors that align with popular governance catalogs. This alignment matters because it minimizes reconciliation work during later stages of the pipeline. When viewed against ad hoc extractors, the schema-first approach consistently lowers error rates in downstream validation steps. I cross-referenced product briefs and analyst notes to confirm this trend. Reliability and schema fidelity are the two levers enterprises press hardest.
AI-assisted platforms with strict governance hooks
AI-assisted extraction remains attractive for pulling from semi-structured and unstructured sources, but buyers push back on hallucination risks without governance hooks. Leading platforms couple model-driven extraction with strict provenance, access control, and versioned schemas. Pricing discussions increasingly include governance as a differentiator, not an afterthought. A notable pattern is vendors that expose model-agnostic connectors to data catalogs, enabling traceability from source to catalog entry. From the literature and vendor documentation, this combination appears to reduce rework and policy drift. Governance-first design helps tame AI variability. Query-time validation against catalog schemas cuts downstream rework.
UX and integration as production determinants
Even the best extraction capabilities will fail to deliver in production if the UX and integration surface are weak. Buyers favor tools with developer-first APIs, robust SDKs, and out-of-the-box connectors to popular ETL and data governance platforms. Visual data lineage and editable mapping wizards shorten the path from discovery to deployment. The most successful tools offer REST and GraphQL endpoints, plus native connectors to data lakes, warehouses, and metadata catalogs. This is not merely convenience. It affects cycle time for data teams and the stability of automated governance policies. Production readiness hinges on integration quality. Developer-friendly APIs accelerate deployment cycles.
Most buyers in 2026 value tools that pair schema fidelity with governance hooks, not just raw extraction accuracy. This pairing reduces the cost of compliance and accelerates time to insight in enterprise workflows. Expanso’s 2026 roundup notes the same tension between capability and governance, highlighting the push toward integrated toolchains rather than isolated extractors. Integrated toolchains beat standalone extractors for enterprise scale.
In line with benchmarks I studied, the market shows a split between specialist extractors and AI-enabled platforms. The strongest incumbents stay aligned with established data catalogs and policy engines. The newcomers push hard on end-to-end usability and faster integration, yet still need solid governance rails to be trusted in regulated environments. Mixing speed with governance remains the practical limit on acceleration. How CRM email integration affects data consistency and delivery guarantees in 2026
Data quality and governance in extraction workflows
Data quality today hinges on traceability, provenance, and reproducibility. In enterprise pipelines, these aspects are no longer optional. They’re embedded requirements for audits, compliance, and operational resilience. I cross-referenced recent benchmarks and literature that consistently flag end-to-end lineage as a first-class capability, not a nice-to-have add-on. The takeaway is clear: you cannot trust outputs without knowing where they came from and how they were produced.
Why traceability matters in practice
Traceability starts with a deterministic record of each data item’s origin and every transformation it experiences. In 2026, teams increasingly rely on centralized metadata graphs that tie each field back to source systems, schema definitions, and validation steps. This visibility helps explain why a given JSON output looks the way it does, and it makes audits faster when governance policies change. A robust lineage layer also supports reproducibility: rerun a pipeline with the same inputs and you should obtain the same outputs, down to the same JSON shape. Provenance and reproducibility are table stakes in modern pipelines.
Standardized schemas and validation cuts
Consistency across sources hinges on standardized schemas and explicit validation rules. In practice, teams adopt schema registries and contract testing to guard against drift. When schemas evolve, forward and backward compatibility checks keep downstream consumers from breaking. The result is smoother ETL flows and fewer exposure points for misaligned JSON or tabular outputs. A common pattern is to codify schemas as part of data contracts and enforce them through automated tests that run on every push. This minimizes runtime surprises and speeds incident response.
Automated checks for drift and misalignment
Automated checks catch schema drift early, before it propagates. Industry chatter and benchmarks point to continuous validation as a core discipline: automatic diffs against a canonical schema, alerting when a field appears in a payload that doesn’t meet the contract, or when an output deviates from the expected JSON structure. As outputs increasingly travel through multiple stages, automated checks become the guardian that keeps schema fidelity intact. In practice, this means you’ll see recurring patterns like schema drift alerts, automated schema evolution workflows, and enforced normalization across data sources.
I dug into the benchmarks and found that mature toolchains emphasize three elements: a solid schema registry, contract tests that run in CI, and a suitable provenance store. This trio helps teams stay aligned as sources change and as downstream usage expands. For governance teams, the payoff is measurable: faster audits, fewer hotfixes, and clearer data lineage. How to create a visual identity that sticks in 2026
Traceability is not optional in 2026. It’s the backbone of trustworthy data.
Another practical touchstone comes from industry write-ups that compare tools on schema fidelity and validation practices, underscoring that consistent validation rules reduce drift and enable reliable governance at scale. https://www.firecrawl.dev/blog/best-structured-data-extraction-tools
Finally, for enterprise-context perspectives, the overview of data-extraction tool suites highlights how standardized schemas and contract-based checks map directly to governance objectives and risk reduction. https://expanso.io/blog/data-extraction-tools/
If you’re implementing today, treat data contracts as code, tie outputs to source-of-truth lists, and automate drift detection with immediate remediation hooks. You’ll reduce ambiguity and accelerate both compliance workflows and day-to-day operations. And yes, links on the page may earn a commission.
What changes if you act now
Structured data extraction in 2026 leans into automation and explainability. I’ve observed a shift toward hybrid pipelines that combine rule-based parsing with AI-assisted classification, which reduces manual tuning without sacrificing accuracy. The payoff is a smaller maintenance burden and faster adaptation to new schemas. The bigger pattern is that teams deploy modular extractors tied to governance layers, so data quality improves even as data sources multiply. You’ll notice fewer brittle scrapers and more resilient mappings, especially for multi-source feeds. How to generate engaging content automatically with AI in 2026
One move that matters is investing in sample-driven validation at the schema level, not just data-level checks. This helps catch drift early and keeps downstream analytics trustworthy. Even with the advantages, expect ongoing friction around data lineage and access controls. The downsides are real and widely discussed in 2026 reviews. I’m not seeing price or performance numbers here, only direction and trade-offs.
Backup strategy / What to try this week
- Audit your current extraction graphs and label any brittle nodes.
- Add a lightweight lineage snapshot for the top three data sources.
- Pilot a small AI-assisted extractor for a single schema and compare maintenance time to your legacy approach.
- Review vendor governance features and enable explainability flags where available.
Notes: links on the page may earn a commission.