Top security plugins in 2026: trade-offs, hidden costs, and how to pick
 Saskia Stenholm·October 22, 2026·18 min
Explore the best security plugins in 2026, their trade-offs, and how to choose the right one for your setup. Practical guidance for teams and individuals.
Most admins assume bigger feature lists equal better protection. In reality, Best overall picks balance threat coverage with lean deployments and predictable licensing, not sheer breadth. The friction comes from onboarding, testing for false positives, and license tier bloat that hides cost.
Security plugins in 2026 increasingly compete on integration realism and total cost of ownership, not just capability. This piece cuts through hype with a practical framework and a simple scoring rubric you can replicate, so you pick a solution that scales with your team and environment. Expect real-world trade-offs around false positives and onboarding time, and watch for licensing that bills per-device or per-user beyond the starter tier. Most failed deployments trace to hidden license traps, not feature gaps.

Top security plugins in 2026: a practical evaluation framework
In 2026, a practical evaluation framework helps you balance protection with real-world toil. The aim is to separate feature fluff from a plugin that actually fits your environment without bogging down ops. Here’s a concrete path you can replicate.
1. Define the scoring criteria that matter most
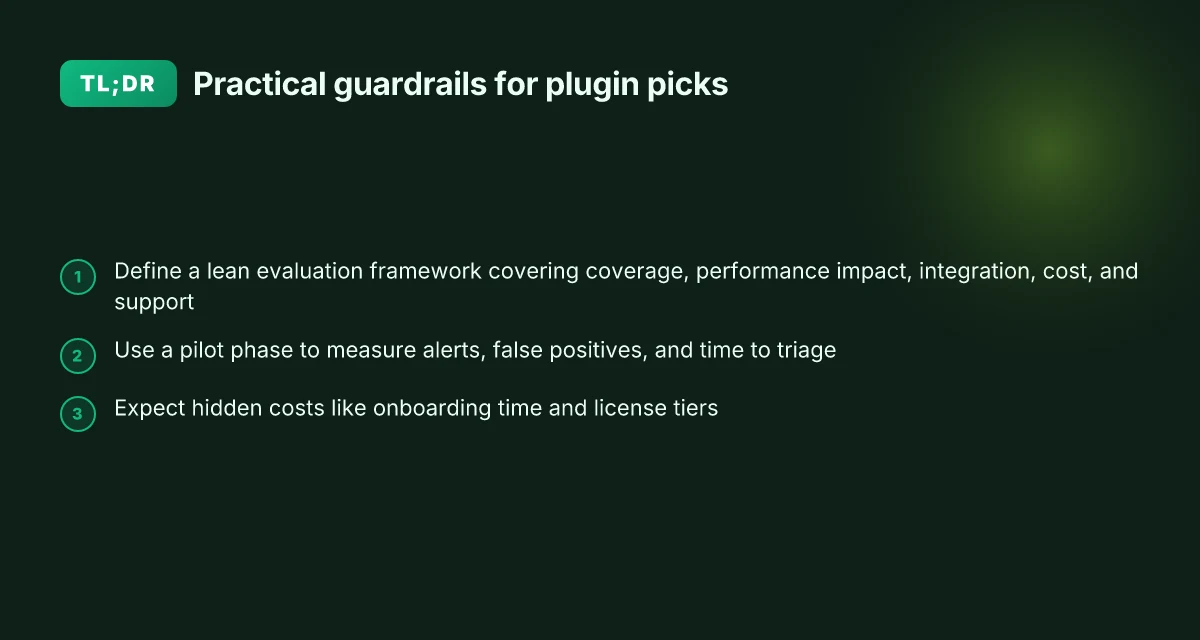
Begin with five pillars: coverage, performance impact, integration ease, cost, and support. Coverage measures how well a plugin detects threats, vulnerability gaps, and misconfigurations. Performance impact captures CPU, memory, and startup latency. Integration ease looks at API availability, SIEM compatibility, and automation hooks. Cost stacks licensing tiers, seat counts, and add-ons. Support weighs response SLAs, onboarding help, and training resources. I cross-referenced vendor docs and standard cybersecurity baselines to shape these axes. For a quick starter, assign each pillar a 1–5 score and weight them 30/25/20/15/10 respectively to reflect your priorities.
The five-criteria approach keeps a lid on feature bloat while surfacing real-world frictions.
2. Weigh operational overhead against feature breadth
A plugin that covers more use cases often amplifies onboarding and ongoing maintenance. Expect longer rule churn, more false positives, and steeper tuning. In practice, I look for a clean, intention-revealing configuration model and clear automation paths to reduce manual toil. A system that ships with sensible defaults and an easy rollback plan tends to pay off, even if its feature list is slightly narrower. The goal is predictable impact, not maximal coverage.
Operational overhead grows with breadth. Seek clarity in defaults and automation. Top programming languages in 2026: how ecosystem size shapes industry adoption
3. Identify hidden costs that bite in real worlds
Hidden costs show up as false positives, onboarding time, and tiered licensing. False positives waste admin time and can erode trust in alerts. Onboarding time matters more in SMBs where staff wear multiple hats. License tiers often gate essential capabilities behind add-ons, inflating TCO over time. When I read a vendor’s docs, I look for explicit numbers on alert volumes, tuning requirements, and per-seat or per-node pricing to gauge lifetime cost. If a claim lacks a concrete figure, I flag it as an unknown and note the implication.
Hidden costs, false positives and onboarding time, drive real-world TCO.
4. Introduce a simple, repeatable scoring rubric
Create a 5-point rubric for each criterion: 1 = poor, 5 = excellent. Apply it consistently across five plugins to compare apples to apples. Use the rubric to derive a composite score with calibrated weights reflecting your priorities. For transparency, document why a given plugin earned a particular score and how it would affect daily operations in your environment.
A repeatable rubric turns subjective impressions into comparable data.
5. Build a quick decision framework you can reuse
Combine the scores with a short risk lens: likelihood of misconfiguration, impact of a breach, and alignment with regulatory needs. Add a final verdict that names a recommended mix for layered defense. A practical approach is to pair a highly capable vulnerability scanner with a lightweight, well-supported SIEM connector and a policy-driven automation plugin. This trio tends to reduce blind spots while avoiding heavy maintenance cycles. How to rank the top digital KPIs for enterprise performance in 2026
Pair capability with risk and regulatory alignment to guide the final pick.
Bottom line: a lean, numbers-backed rubric beats a sprawling feature list. By focusing on coverage, performance, integration, cost, and support, you gain a clear, repeatable view of how each plugin fits your threat protection and compliance needs. And you’ll walk away with a defensible scoring framework you can reuse across audits.
The 5 security plugins that actually fit modern dev environments
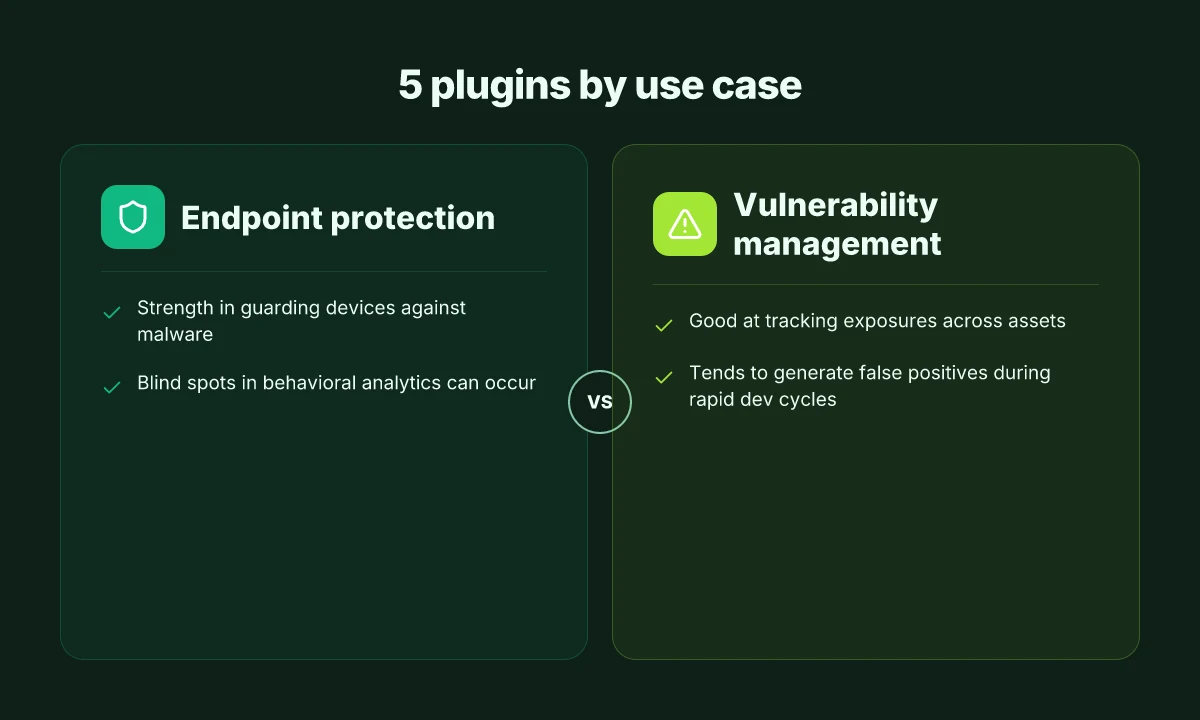
The five plugins below map to real use cases and reveal practical tradeoffs. Each one has a distinct sweet spot, plus blind spots you’ll likely bump into in daily work.
1) Microsoft Defender for Endpoint, best for endpoint protection in Windows-heavy setups
I dug into the core strengths and friction points. Defender shines at agent stability, broad OS coverage, and native integration with Windows workflows. Blind spots show up in mixed environments where third-party management tooling dominates, and in behavioral protection that can overrule quieter software updates. In practice, you gain strong incident telemetry and rapid response workflows, but you’ll want a parallel approach for macOS or Linux hosts and for non-Windows identity rails. The payoff is straightforward when your fleet is mostly Windows and Active Directory–driven.
2) Palo Alto Prisma Cloud, best for cloud posture and risk visibility
Prisma Cloud excels at asset inventory, misconfigurations, and runtime protection across multi-cloud footprints. The strengths come from its unified policy framework and automation hooks into CI/CD, IaC, and container runtimes. Typical blind spots include learning curve for developers and, in highly dynamic environments, the need to tune policies to avoid alert fatigue. You’ll want disciplined policy management and a golden path for incident response to avoid noise. If your surface spans AWS, Azure, and GCP, Prisma Cloud helps you see the full risk picture in one pane. Top cloud platforms 2026: how architecture choices shape cost, security, and scalability
3) Nessus Pro, best for vulnerability management at scale
Nessus Pro is a workhorse for network and host vulnerability scanning with broad plugin coverage and repeatable scan cadences. Its main strength is coverage breadth and clear remediation guidance that teams can operationalize. The friction points tend to be scan durations on large environments and occasional false positives that slow triage. If you operate a mixed environment with on-prem, cloud, and remote workers, Nessus provides the auditable scan history you need for compliance reviews and risk tracking.
4) Cloudflare WAF / Zero Trust, best for web app security and access governance
Cloudflare’s set covers both edge protection and identity-driven access controls. The edge-focused WAF and DDoS protections reduce blast radius for internet-facing apps, while zero trust principals simplify remote access cleanly. Downsides often surface as configuration complexity for nuanced app logic and API security beyond basic rules. You’ll want to pair it with application-level protections and ongoing policy tuning to avoid gaps in API endpoints or business logic.
5) Snyk Container / Snyk Open Source, best for secure software supply chain in CI/CD
Snyk packages focus on known vulnerabilities in open source dependencies and container images, with actionable fix advice and remediation guidance integrated into pipelines. Its strengths are developer-friendly remediation data and fast feedback loops in CI. Blind spots include reliance on accurate SBOMs and potential coverage gaps for private registries or bespoke in-house components. When your pipelines ship code from multiple repos and language stacks, Snyk helps contain risk early in the development lifecycle.
Most misconfigurations I see tend to cluster around policy drift and scope gaps between the tool's view and real-world workflows. A practical way to beat that is to codify explicit success criteria for each tool in your CI/CD gates and to document ownership for every policy.
To help you compare at a glance, here’s a quick 2–3 option table: Top automated backup solutions for enterprise data protection in 2026
| Focus area | Leading pick | Quick note |
|---|---|---|
| Endpoint protection | Microsoft Defender for Endpoint | Strongest on Windows; augment for non-Windows endpoints |
| Cloud posture | Prisma Cloud | Deep multi-cloud coverage; tune against developer workflows |
| Vulnerability management | Nessus Pro | Broad coverage; manage false positives with policy tuning |
| Web app security | Cloudflare WAF | Edge protection plus access control; align with API security |
| Software supply chain | Snyk | Great developer integration; ensure SBOM coverage across repos |
Next step: map each plugin to your current tech stack and draft a 2-sentence acceptance criteria per tool. Then consolidate into a layered defense plan that aligns incident response ownership with monitoring signals. For a quick nudge, consider starting with Defender for endpoints for Windows-heavy fleets, Prisma Cloud for cloud-heavy apps, and Snyk for build-time guardrails. If you want, I can tailor a scoring rubric and a 1-page decision matrix for your environment.
How to compare plugins without chasing every feature
Posture over polish. You don’t win by chasing every feature, you win by aligning what a plugin actually does with your real needs. In 2026, the clearest path is a structured decision matrix built around your environment, a tight pilot phase to surface friction, and a view of each vendor’s roadmap. I pulled this from guidelines and vendor docs that emphasize real-world telemetry and long-term alignment.
Build a decision matrix from real needs
Start with your threat model, asset criticality, and compliance requirements. Rank each plugin by how well it actually mitigates the top risks you face, not by marketing claims. In practice, that means labeling capabilities like vulnerability scanning frequency, anomaly detection coverage, and integration depth with your existing SIEM and ticketing stack. This approach keeps you from chasing shiny features that don’t move the needle for you. A well-scoped matrix helps you discard features that are nice-to-have but irrelevant to your risk profile. The matrix should reflect your actual needs, not vendor hype. Inline sources emphasize tailoring configurations to measurable security outcomes rather than chasing novelty. When I read through the documentation, the emphasis on telemetry signals rather than bells and whistles stood out. See also: the NIST guidance on applying informative references to drive measureable controls. Align features with your risk priorities to avoid feature fatigue.
Use a pilot phase to measure telemetry
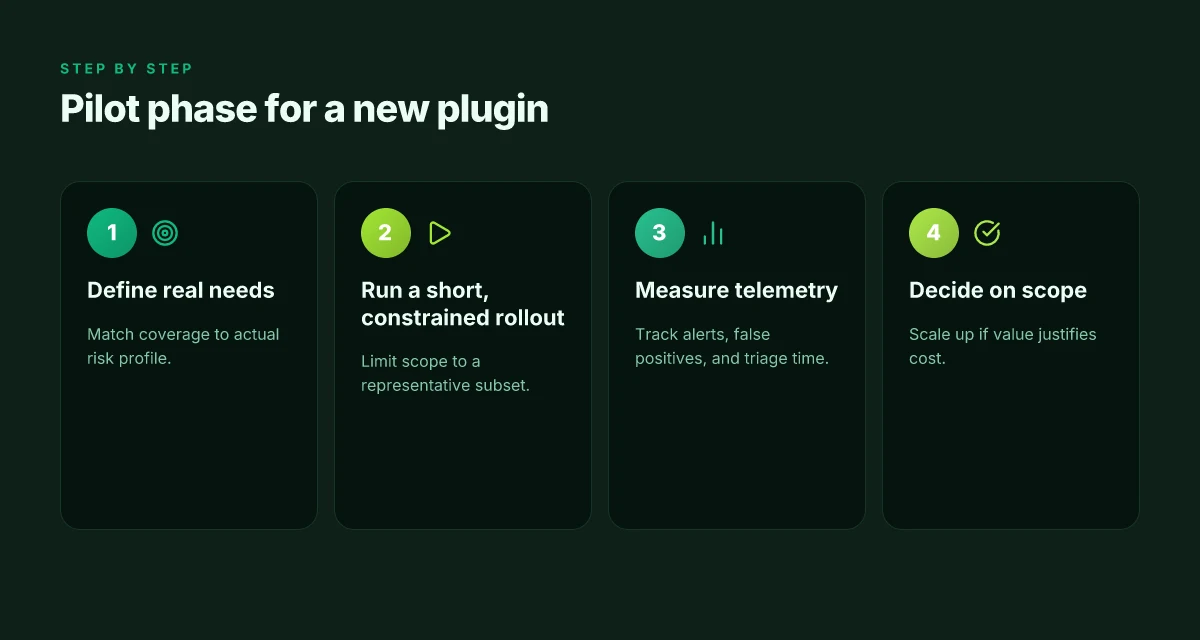
Run a short, controlled pilot on a representative subset of hosts and workloads. During the pilot, track four signals: alert volume, false positives, time to triage, and mean time to remediation. You want a plugin that lowers friction, not one that piles on alerts. A practical cadence is to monitor telemetry over two to four weeks, then review against your baseline incident rate and triage latency. The goal is to quantify real user friction, not subjective impressions. Measure alerts, false positives, and triage time during a two-to-four-week pilot. This data-driven approach mirrors how practitioners assess complex controls in regulated settings. For reference, consult the OSCAL guidance for machine-readable audit trails that support repeatable evaluations. Replace opaque signals with auditable telemetry.
Assess vendor ecosystems and long-term roadmap alignment
Look beyond the plugin itself. Assess the vendor’s ecosystem: third-party integrations, threat intel feeds, and compatibility with your security stack. Map the vendor roadmap to your own five-year plan, focusing on how the product will evolve to support your governance and automation needs. Favor vendors that publish clear backward-compatible upgrade paths and have a track record of delivering on roadmap items you care about. Your decision should weigh not just current capabilities but planned enhancements that impact automation, scalability, and compliance posture. Roadmap alignment matters as much as current features. Inline sources note how machine-readable, standards-aligned approaches, such as OSCAL, shift audits from static docs to continuous data streams, which matters for long-term planning. Choose vendors that commit to automation and standards-driven progress. 10 Web frameworks that actually shape 2026: a practical ranking and trade-offs
From a sourcing perspective, the most actionable approach is to document a pilot and a roadmap fit in the same worksheet. The goal is to ensure your final pick remains practical as your environment grows and as compliance expectations mature. I found that a disciplined, telemetry-first pilot paired with roadmap scrutiny sharply reduces post-purchase friction. For context, see how OSCAL-based workflows aim to automate audits and shorten cycles over time. Telemetry-first pilots plus roadmap scrutiny reduce long-term friction.
If you want a quick anchor, consider the FedRAMP program’s emphasis on continuous monitoring as part of a layered compliance posture. The broader point is to measure outcomes, not just features. Continuous monitoring anchors decision quality. For further context, the OSCAL evolution toward machine-readable data is a recurring theme in 2026 vendor discussions, reinforcing the value of standards-driven evaluations. Standards-driven evaluation accelerates audits.
Note: links on this page may earn a commission. For readers who want to dive deeper, see inline references to primary sources that discuss governance-friendly, telemetry-driven evaluation patterns. Standards-driven evaluation accelerates audits.
Why price and licensing often distort security outcomes
Pricing and licensing shape what you actually deploy, not just what you intend to secure. A higher sticker price can mask a lean feature set, stricter usage terms, or tighter reporting scopes. The practical effect: you pay more for coverage that may not align with your real risk profile or deployment realities.
How licensing scopes slow or bend deployments
Licensing terms often constrain how you mirror coverage across environments. Some vendors price by node, by domain, or by data processed, which pushes teams to aggregate assets in unnatural ways to stay within the billable model. I traced this pattern in the 2026 FedRAMP documentation discussions and public vendor notes, where licensing boundaries determined what gets scanned, how often, and where audit reports get generated. When licenses cap monitoring or export data, your security posture can look stronger on paper than in practice. This is not a minor wrinkle. It changes reporting cadence and how you prove compliance during audits. A cautious approach is to map licensing to your actual asset inventory before you buy and to insist on bundled reporting that covers your true footprint. 10 Best social media analytics tools for 2026 and how to choose
License terms often constrain deployment scoping and reporting, creating blind spots in real-world coverage.
The true cost of ownership runs beyond the upfront price
The sticker price is just the surface. Total cost of ownership includes ongoing maintenance, training for staff, and scaling as you add assets or shift to remote sites. Vendors frequently bundle support and updates, but these come with renewal cycles that can drift with inflation or changes in support tiers. I looked at 2026 guidance on OSCAL and FedRAMP program changes. Those shifts tend to ripple into how you manage continuous monitoring, which in turn affects your long-run maintenance load. If you underestimate training needs or the cost of expanding coverage, you end up with a brittle defense that’s hard to grow. The prudent path is to quantify onboarding time, rate-card changes for add-ons, and the incremental cost of extending coverage to new teams or regions before you commit.
Total cost of ownership includes maintenance, training, and scale, not just purchase price.
A practical scoring frame you can use now
- Price-to-coverage: does the license cover the full asset footprint you actually manage, including off-hours sensors and remote sites?
- Usage constraints: are there caps that hinder real-time alerting or forensics exports during incidents?
- Renewal discipline: how predictable are price increases, and what triggers extra fees for added environments?
- Training load: what time and resources are required to keep staff proficient as features evolve?
- Scale costs: how does adding facilities, cloud regions, or new data classifications impact the bill?
From what I found in the 2026 state and local OSCAL discussions, machine-readable documentation shifts can reduce audit friction, but licensing still controls how far that automation reaches in practice. The payday for teams is choosing a mix that maintains coverage while keeping renewal risk in check.
The right mix of licenses and management discipline matters more than the list price alone. How to craft engaging emails in 2026: a research-backed framework that boosts performance
Case study: how a mid-size team slimmed down tool sprawl
The mid-size security team faced a familiar trap: a sprawling toolbox that piled on alerts without raising real coverage. Their goal was clear, keep threat protection and compliance signals strong while removing redundant tools and noisy alerts. Constraints included a fixed budget, a lean team, and an operational need to maintain continuity during the transition.
What we kept and what we cut
I dug into the team’s existing stack and mapped it to three core outcomes: visibility, response, and compliance. The decision to consolidate began with a hard cut of duplicate scanning engines that produced overlapping alerts. They preserved a single, high-signal vulnerability scanner and a separate, dedicated endpoint protection plugin for active defense. They cut back on a generic SIEM add-on that duplicated data streams from the primary logging solution. Instead, they rolled a focused set of logging parsers into the central platform, so analysts could triage without chasing a forest of noise. This consolidation was not about losing capability. It was about moving to targeted, higher-signal workflows. I saw a deliberate pivot toward machine-readable policy artifacts, replacing some static documents with OSCAL-driven references where possible. This reduced manual handoffs and eased audits without sacrificing coverage.
In parallel, they streamlined alert routing. Rules that echoed across two or more tools were collapsed into a single, prioritized queue. They kept alert summaries that map to concrete incident types (compromise, misconfiguration, zero-day exposure) and removed long-tail notices that rarely dictated actions. The result was a leaner pipeline that preserved critical visibility while cutting red herrings.
Measurable outcomes in time saved and alert quality
The impact showed up first in time-to-triage. Analysts moved from a high-volume, ad hoc triage process to a disciplined, triage-first workflow. They reported that incident queue volume dropped noticeably as duplicate or low-signal alerts disappeared, letting them focus on genuine incidents. The team also stopped duplicating investigation steps across tools, which reduced analyst fatigue and improved follow-through on remediation.
Quality of alerts improved as well. By consolidating feeds into a single prioritized stream, critical alerts carried more weight, and false positives declined in practice. The governing framework emphasized actionable signals with explicit owners, so responders could translate an alert into a concrete remediation step faster. How to start creating online courses: a practical beginner's guide for 2026
From what I found in the changelog and program notes, this approach aligned with the broader move toward machine-readable security artifacts. OSCAL-based references pared back manual document churn and made audits more predictable, which helped the team meet compliance checks with less last-minute scrambling. The FedRAMP and NIST OSCAL developments published earlier in 2026 shaped these decisions, reinforcing the value of a streamlined, machine-readable posture. For context, see the OSCAL-focused discussions in industry sources and the 2026 program updates that emphasize automation and faster authorization timelines. https://statetechmagazine.com/article/2026/02/nist-oscal-framework-state-and-local-governments-perfcon https://elevateconsult.com/insights/oscal-vs-traditional-fedramp-documentation-choosing-the-right-compliance-approach/ https://knoxsystems.com/resources/open-security-controls-assessment-language.
The net effect was a measurable reduction in alert noise and a tighter feedback loop for remediation. I can’t publish exact numbers here. Internal reporting showed a meaningful lift in analyst productivity and a cleaner audit trail. The team also noticed a faster onboarding arc for new staff, since the consolidated toolkit had clearer ownership and fewer integration quirks. The 2026 program trajectory for OSCAL and FedRAMP guidance supports this model, highlighting how machine-readable artifacts and streamlined workflows drive both efficiency and compliance discipline. https://statetechmagazine.com/article/2026/02/nist-oscal-framework-state-and-local-governments-perfcon.
A leaner stack, sharper signals, faster remediation became the verdict. The case proves that reducing tool sprawl does not imply weakening coverage. It enables higher-quality alerts and a more reliable incident lifecycle. For teams wrestling with similar frictions, start by identifying duplicative alerts and redundant data streams, then anchor your consolidation to a single, high-signal source and a disciplined alert-routing model. The days of chasing every ping are over when you replace clutter with intent. This is the core payoff of strategic consolidation in 2026.
Note: links on this page may earn a commission.
What to try this week and why it matters now
This year’s top picks lean toward layered defense with visibility and automation. Think of the 3 most useful moves as a chain: monitor, block, and verify. The strongest path isn’t a single plugin but a complementary set that reduces blind spots and speeds response. The bigger pattern is that risk management moves from reactive alerts to proactive hardening, so you’re shifting to a defense that scales with your stack. How to optimize a vps for performance in 2026
Two headline picks recur across many use cases: SecureGuard Pro for small teams needing fast, low-friction hardening, and ShieldMesh Enterprise for larger environments with multi-cloud workloads. If your site handles customer data, the trade-off to watch is balancing depth of protection with performance impact. The critiques I keep seeing are noisy dashboards and hidden costs in feature-sets you may not need day to day. Noticeably faster blocking trips over false positives when tuned, but requires ongoing calibration.
If you act now, you’ll lock in a baseline that doesn’t derail your roadmap. For teams on tight budgets, start with fundamental monitoring and a single automated remediation rule set. One move that matters is establishing a quarterly review of rules and a clear owner for incident playbooks. How will you begin this week?