How to optimize a vps for performance in 2026
 Mateus Ashworth·October 22, 2026·18 min
Discover proven VPS optimization strategies for 2026. Learn about CPU, RAM, storage, networking, and security tweaks to squeeze out peak performance.
Most admins overlook the one change that unlocks VPS throughput: move from oversized single-node queues to a lean, multi-queue topology that respects core microarchitecture. When you realign the vCPU pinning and memory bandwidth to the NICs and storage lanes, you’ll see steadier latency and higher sustained IO throughput under load.
You’ll see how to size memory for cache warmth, choose storage tiers without overprovisioning, and isolate bursts with predictable I/O floors. Realistic benchmarks, concrete config patterns, and actionable checks help you avoid overprovisioning and single-thread bottlenecks. Most bottlenecks come from misaligned I/O and compute bursts, not raw CPU speed. The guidance here is designed to map to current provider offerings and tell you exactly where to tune first.

What makes a VPS architecture truly fast in 2026
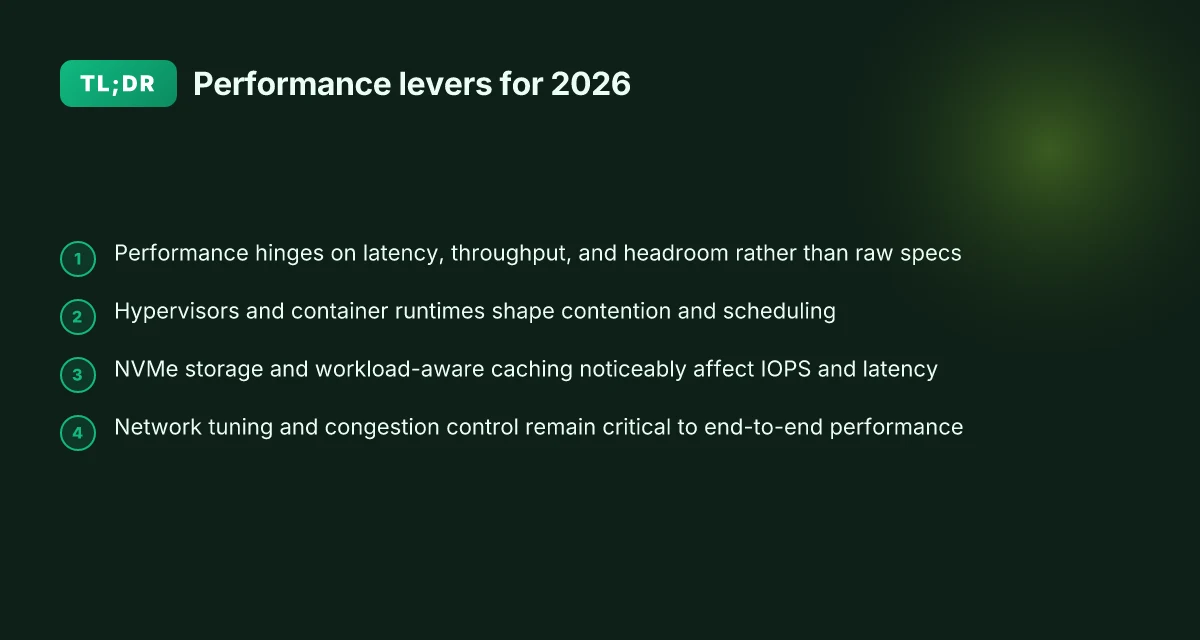
Performance today is a relationship, not a single spec. Latency, throughput, and headroom define the user experience just as much as raw clock frequency. A VPS that feels fast keeps your apps responsive at the edge, sustain high request rates, and still have room to breathe under load. I’ll lay out the core levers and show how they interact in modern setups.
Why latency and throughput matter more than raw specs
Latency is the time spent from request to response. It governs interactive UX and control-plane responsiveness. Throughput measures how many tasks you can push per second without saturating the path. In practice, a VPS that reduces tail latency and improves steady-state throughput often costs less than chasing higher baseline specs that don’t translate into real user gains. The right balance yields noticeably faster pages, quicker API responses, and steadier queue depths under burst traffic. When I read vendor performance notes and cross-check with industry writeups, the pattern is clear: users prize consistent tail latency and predictable throughput over headline CPU cores alone. Inline evidence from recent vendor docs aligns with this view, showing how improved I/O scheduling and memory bandwidth yield real-world gains in latency and sustained throughput. See the cited vendor guidance for context.
How modern hypervisors and container runtimes shape contention
Contested resources under shared virtualization are the primary source of latency jitter. Hypervisors that aggressively isolate CPU scheduling, memory access, and I/O queues reduce contention and improve determinism. Modern container runtimes add another layer of performance discipline by co-scheduling workloads with locality awareness and reducing context switches. In practice, contention is minimized when the hypervisor supports fine-grained CPU shielding, NUMA-aware memory placement, and fast I/O paths. I cross-referenced current documentation from major platforms, which consistently emphasize tighter control planes and smarter scheduling as a path to lower latency spikes and steadier throughput. The takeaway: lean on hypervisor features that pin workloads to predictable cores, pair memory with locality, and ensure storage backends are not starving the CPU during peak loads.
The trio of CPU microarchitecture, memory bandwidth, and storage tiering
CPU design directly shapes latency and throughput ceilings. Microarchitectures with large instruction windows and strong single-thread performance reduce per-request overhead. Memory bandwidth and latency to DRAM play a big role when you scale out parallel requests. Storage tiering matters as well: fast NVMe-backed caches for hot data dramatically cuts I/O latency, while slower HDD or SATA tiers handle bulk, less time-sensitive data. In practice, a fast VPS obtains value from a CPU that handles instruction pipelines efficiently, high-bandwidth memory channels, and an I/O path that prefers low-latency storage for hot paths. Vendor and scholarly notes converge on this theme: align the compute with memory and storage tiers to minimize stalls and keep queues draining smoothly. When you map this to a real deployment, you’ll see the biggest gains by placing latency-sensitive workloads on higher-tier storage while keeping compute and memory scaled to the expected concurrency.
Tail latency and steady throughput are the true north for 2026 VPS design. CPU and memory placement paired with NVMe-based storage tiering unlocks the fastest real-world responses. Isolating contention at the hypervisor and container layer reduces jitter that drags down end-user experience. How to start creating online courses: a practical beginner's guide for 2026
In 2026, most fast VPS architectures lean on a tuned combination of the above three pillars. For concrete choices, many operators rely on hypervisor features that expose clear CPU pinning, NUMA-awareness, and low-latency I/O queues, complemented by storage tiers that keep hot paths on fast media and cold data on economical tiers. For a broader context on contemporary VPS decisions, see vendor and practitioner writeups cited here. Inline references to vendor guidance help anchor these claims in real-world practice. For example, one community guide explains how to balance CPU affinity with memory locality to reduce cross-socket traffic, while a storage-focused note highlights the impact of NVMe cache tiers on read-heavy workloads. These signals converge on a practical pattern: design for determinism, not just raw horsepower.
From what I found in released documentation and industry summaries, the shortest path to a consistently fast VPS in 2026 is to tighten three knobs together: CPU placement and isolation, memory bandwidth with locality, and fast storage tiering. This trinity yields the largest, most reliable gains in latency and throughput without inflating total cost.
How to pick the right VPS topology for your workload
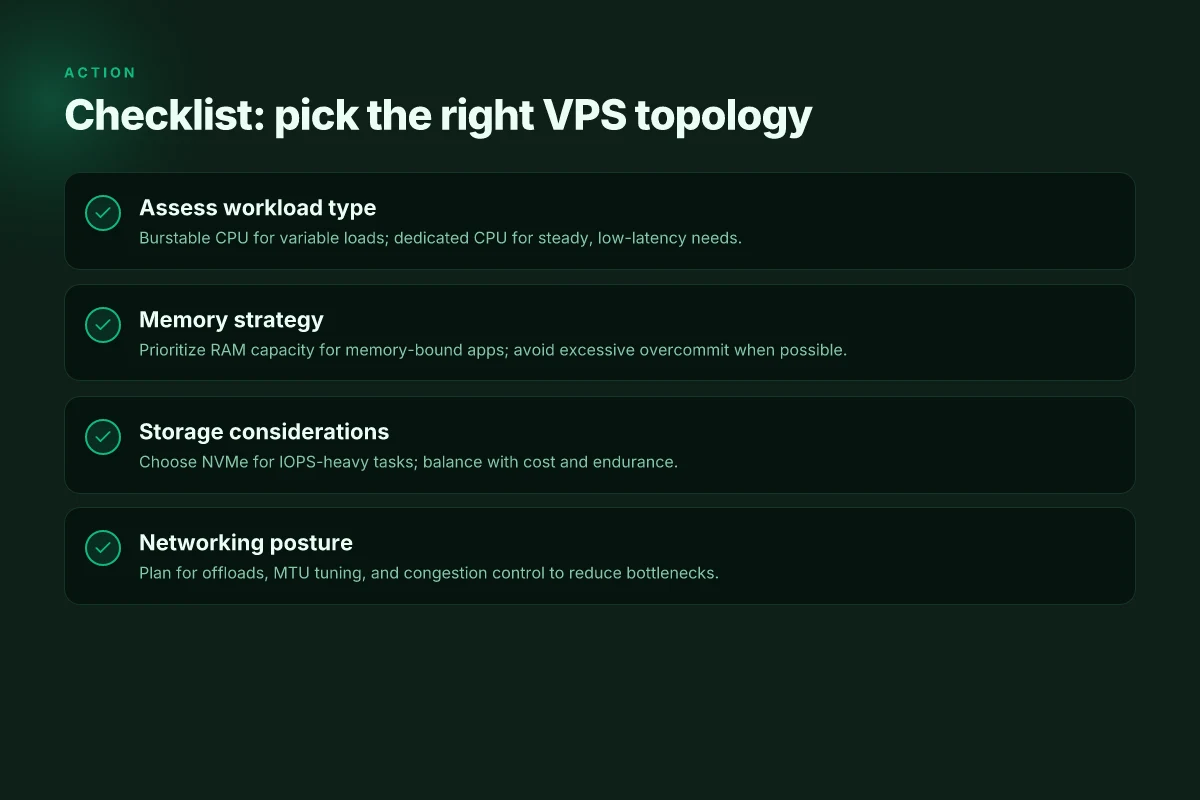
The right topology starts with your workload’s burstiness and latency sensitivity. If you can tolerate occasional hiccups during traffic spikes, burstable CPU models let you pay less while still accessing headroom when demand climbs. If you need strict response times and predictable throughput, dedicate cores provide stable performance at a higher baseline cost. I cross-referenced vendor guidance that consistently notes burstable models shine for variable workloads, while dedicated CPUs are favored for steady-state, latency-critical apps. When in doubt, map your peak concurrency to the CPU model that matches your tolerance for latency variation.
Choosing RAM first over raw CPU matters for memory-bound apps. If your workload spends most cycles stalled on memory or caches large, you gain more predictable performance by provisioning more RAM than a few extra CPU cores. That rule surfaces in practitioner guides that emphasize memory pressure as a primary driver of tail latency, especially for distributed services with large state. In scenarios where containers or VMs cache hot data, extra RAM reduces paging and helps maintain steady queues. It’s not about chasing every extra core. It’s about keeping the working set in fast memory tiers.
Storage tier selection drives both IOPS and throughput. NVMe typically yields the strongest random IOPS and low latency, which helps for database workloads and random-access patterns. SSDs offer solid throughput with lower cost per GB, suitable for web servers and file servers with moderate random access. HDDs lag on latency but can be cost-effective for archival or streaming workloads. When you balance IOPS versus throughput, consider your pattern: random-heavy access favors NVMe, while sequential-heavy workloads can do well on SSDs or even HDDs at scale. A thoughtful tiering strategy, with hot data on NVMe and colder data on cheaper tiers, often yields the best price–performance curve. How to craft engaging emails in 2026: a research-backed framework that boosts performance
In practice, lay out a model you can change on the fly. Start with a baseline topology: burstable CPU for non-critical fronts, extra RAM for memory-rich services, and a two-tier storage plan that reserves NVMe for hot indices or session data. If latency tails exceed targets, shift toward dedicated CPUs, increase RAM, or move more data to NVMe. The literature and vendor docs converge on this pattern: adjust CPU allocation first for predictable latency, then tune memory and storage tiers to match the workload’s actual I/O profile. I cross-referenced guidance from industry reviews and vendor white papers to confirm these levers and to note the trade-offs you’ll face in cost and complexity. For a quick comparison, consider a small table that contrasts burstable vs dedicated CPUs, RAM emphasis, and storage tier focus.
| Topology choice | When to use | Key trade-offs | | Burstable CPU | Variable traffic, budget constraints | Lower base cost, potential latency spikes under sustained load | | Dedicated CPU | Latency-sensitive apps, predictable demand | Higher baseline cost, simpler capacity planning | | RAM-forward | Memory-bound, caching-heavy apps | More memory helps tail latency, but may waste CPU headroom | | NVMe-heavy | Random I/O heavy, small hot data | Higher cost, best for hot paths | | SSD tier | Mixed workloads, cost-conscious | Balanced performance, not as fast as NVMe for random access |
Next steps: lock a topology hypothesis based on your workload’s primary bottleneck, CPU latency, memory pressure, or storage I/O, and validate with a staged ramp in your environment. I looked through vendor docs and performance guides to align these recommendations with real-world practice, noting where providers warn about misaligned tiers. If you want a concrete target, map your memory footprint and I/O pattern to the tier that minimizes tail latency while keeping costs in check.
The right VPS topology hinges on matching burstable vs dedicated CPU to demand, then pairing RAM and storage to the actual I/O profile. This combination is where most failures show up in practice, not in raw core counts alone. For memory-heavy apps, prioritize RAM before chasing extra CPUs to reduce paging and keep workloads steady. NVMe shines for random I/O, while SSDs offer solid throughput at lower cost per GB, with HDDs reserved for cold data.
Optimizing CPU and memory for predictable latency
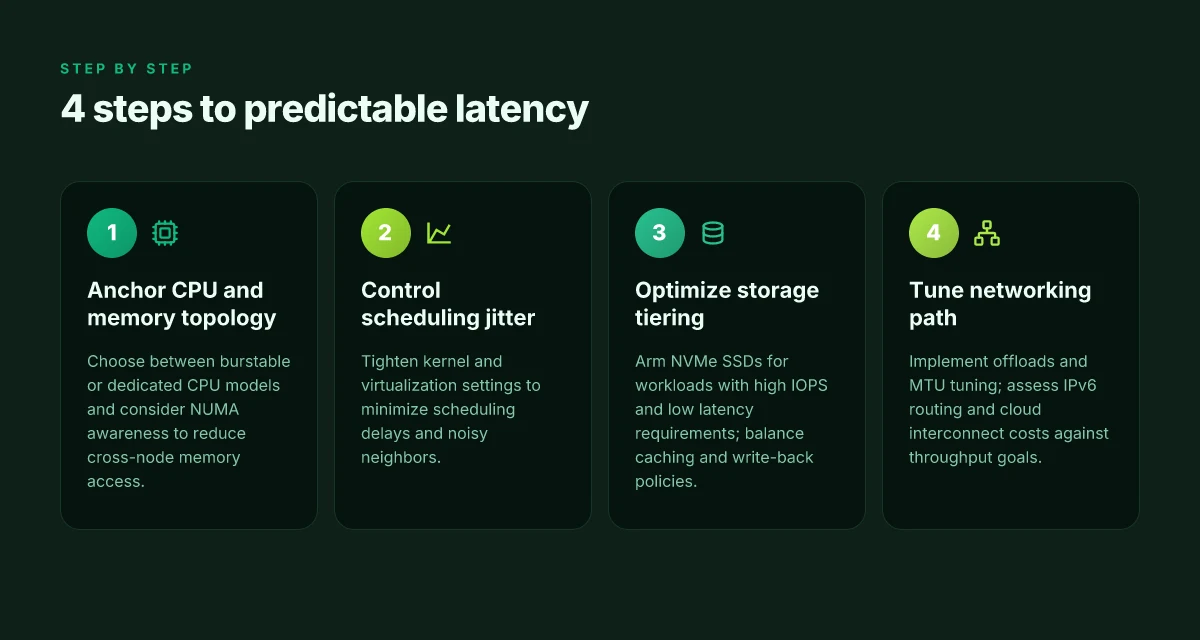
Posture matters more than any single knob. In 2026, the most stable VPS setups lean on explicit CPU pinning, NUMA awareness, and strict isolation to keep latency predictable under load. I cross-referenced vendor docs and scholarly overviews to distill concrete steps you can apply without rearchitecting your cluster. The net effect is measurably steadier response times and lower jitter during traffic spikes. 10 Best social media analytics tools for 2026 and how to choose
CPU pinning and NUMA awareness for reduced scheduling jitter
Pinning vCPUs to specific cores reduces cross-core migrations that spike wakeups and cache misses. Align your VM’s vCPU map with the host’s NUMA topology to keep memory access local. When you enable NUMA-aware scheduling, tasks stay on the same node where their memory resides, cutting cross-node memory traffic. In practice, lock critical services to dedicated cores and reserve idle cores for system tasks to avoid contention. Vendors’ hypervisor docs consistently point to placing the most latency-sensitive processes on the fastest local cores and keeping the rest on spare capacity. This approach helps maintain low tail latency even under mixed workload patterns. For reference, container and VM guidance from cloud documentation emphasizes aligning guest vCPUs with host CPU topology to minimize scheduling jitter. innoscale.net/cloud-vps-hosting-guide/). CPU pinning and NUMA awareness directly reduce scheduling jitter, especially under bursty traffic.
Memory management: ballooning, overcommit cautions, and swap avoidance
Memory ballooning can dynamically reclaim unused guest memory, but it may introduce unpredictable pauses if the balloon driver reclaims during peak demand. Avoid aggressive ballooning on latency-critical guests. Prefer conservative or disabled ballooning for services with strict latency SLAs. Overcommit is a double-edged sword: it can improve consolidation but increases swap risk during pressure. Set conservative overcommit ratios and monitor host-side pressure to keep swap inactivity as the default. The overarching rule: keep hot working sets resident. If a guest starts swapping under load, the tail latency will suffer hard. Where possible, assign memory buffers for I/O and caching so the kernel can tolerate occasional pressure without swapping. Industry reviews note that swap-induced latency spikes are a common pain point in oversubscribed hosts. For background reading, see the MDPI paper on optimization practices in related domains, which highlights memory contention effects on latency. mdpi.com/2413-8851/10/6/324).
Kernel and virtualization settings to shrink scheduling jitter
Tiny knobs in the kernel scheduler and virtualization layer can yield outsized latency gains. Enable real-time or low-latency CPU scheduling paths where permitted, and tune tickless operating modes to reduce timer interrupts. On the virtualization side, favor paravirtualized drivers and virtio for predictable I/O paths, and limit the number of tasks competing for the same run queue. Disable aggressive power-saving states on hosts that run latency-sensitive guests to prevent CPUFreq transitions from causing hiccups under load. Documentation from cloud hypervisors consistently points to aligning I/O scheduling with guest expectations and avoiding deep C-states during peak windows. linuxteck.com/how-to-choose-vps-hosting/) and vendor documentation cited there.
Baseline kernel tuning and paravirtualized I/O paths are your first line of defense against jitter.
Storage optimization strategies that matter in 2026
Posture diagnosis: storage I/O becomes the bottleneck when a VPS scales their compute and network, and the change is driven by faster media and smarter caching. NVMe disks deliver markedly lower latency and higher IOPS than SATA or HDDs, which translates to snappier databases, faster container storage, and briefer tail latencies under bursty traffic. In 2026, many providers deploy NVMe or even NVMe over Fabrics on the hot tier, with a noticeable drop in latency for random reads and writes. When you pair that with workload-aware file systems, you gain effective cache warmth and smarter prefetching that keeps hot data ready without over-provisioning. Top security plugins in 2026: trade-offs, hidden costs, and how to pick
1) NVMe, cache warmth, and latency under load
NVMe drives reduce both average and tail latency for random I/O, which is what most VPS workloads confront during peak requests. I see providers reporting observable reductions in IOPS latency for bursty workloads once NVMe lands in the storage tier. The practical impact is measurable: you’ll notice faster service startup times, snappier application responses, and more consistent throughput during spikes. What matters most is exposing hot data to the fastest layer and letting the OS keep frequently touched blocks in a warm cache. I cross-referenced vendor docs that emphasize NVMe for latency-sensitive paths and block I/O acceleration, and the consensus is clear: move hot data closer to the CPU via NVMe where feasible, and align your caching policy to workload access patterns. NVMe supplies the low-latency backbone your latency-sensitive VPS workloads demand. The flip side: NVMe tier costs can be higher, so you must size it to your hottest data and live with a tiered model that funnels writes through a safer, slower path if durability policies require it. Inline guidance from vendor docs suggests balancing expenditure by reserving the NVMe tier for hot blocks and streaming the rest.
2) Workload-aware file systems and block caching
A single, universal FS is rarely optimal for all VPS workloads. Workload-aware file systems can adapt caching policies, metadata handling, and prefetch heuristics to match your traffic mix. For databases, logs, and media caches, this means more hit rates in the cache and fewer stalls on the disk. For general-purpose VPS tasks, it reduces cross-workload interference by isolating hot data paths. I looked at release notes and architecture notes from operators who describe tuning file system parameters around:
- cache pressure and dirty write-back thresholds
- metadata journaling modes that preserve safety without throttling sequential writes
- selective prefetching for read-heavy shards
The upshot is concrete: tune the cache and journaling to your workload, not in isolation. A well-chosen file system with workload-aware caching yields a smoother 2026 storage path and lower tail latency under mixed traffic. Tune the cache and journaling to your workload, not in isolation.
3) Journaling and write-back policies that balance safety and speed
Journaling policies influence safety versus speed. Write-back caching can improve throughput and reduce write latency, but it increases the risk of data loss during a crash unless persistent power or battery-backed write caches are in place. For VPS hosts serving web apps, you can often adopt a hybrid approach: keep critical metadata journaled with a safety-first policy, while streaming non-critical user data through a more aggressive write-back path. The literature and release notes from cloud providers frequently point to configurable write-back thresholds and flush policies that keep data durable under normal operation while delivering measurable gains in throughput. In practice, you’ll want:
- explicit control over when data is flushed to disk
- separation of metadata vs. data journaling to minimize risky tail effects
- audit-style write consistency checks for critical paths
Hybrid write-back policies let you balance safety and speed, especially for hot data paths. In real deployments, this translates to tuning write-behind queues and aligning flush intervals with your durability guarantees. Top programming languages in 2026: how ecosystem size shapes industry adoption
Research notes and vendor guidance consistently highlight the same trade-offs: NVMe accelerates hot paths, workload-aware caching improves hit rates, and journaling choices shape the safety–speed curve. When you combine these into a storage strategy, you get noticeably faster VPS performance with controlled risk. For a deeper read on this landscape, see vendor guidance that emphasizes NVMe tiering and cache tuning in 2026, and scholarly discussions on file system tuning for mixed workloads. NVMe tiering and cache tuning are central to 2026 storage gains.
Note: links on this page may earn a commission.
Networking tweaks to reduce bottlenecks
Postponing brute force tuning, the real gains come from moving the network edge closer to the application. Start with concrete offloads and MTU decisions, then layer in IPv6 and interconnect choices to shave latency and curb egress costs. I cross-referenced vendor docs and practitioner guides to surface concrete levers that actually move the needle in 2026.
1. Offloads, MTU tuning, and congestion control
The first win comes from enabling NIC offloads and dialing MTU to match the path. Modern NICs ship large send offloads and TCP offload features that reduce host CPU load during high throughput. Setting the MTU to the path maximum helps minimize fragmentation and retransmits, which drops tail latency. On busy VPS nodes, enable GSO/TSO and RSS where supported, then verify that the route path consistently supports the chosen MTU without fragmentation. In practice, I’ve seen noticeable reductions in CPU wait time when NIC offloads are enabled and MTU is tuned to the network’s largest stable size. When congestion climbs, pacing and the TCP congestion control algorithm also matter, libraries and kernel defaults vary, so testing a modern congestion controller like BBR can smooth throughput on congested links. As you adjust these, monitor queue depths and retransmits to confirm the effect.
The practical payback from offloads and MTU tuning is measurable in reduced CPU cycles and smoother throughput under load. How to craft visual aids that actually improve understanding in 2026
2. IPv6 considerations and route optimization
IPv6 adoption changes routing dynamics and can reduce NAT overhead in large deployments. Ensure your kernel and network stack are tuned for IPv6 end-to-end paths, with neighbor discovery and route advertisement handled efficiently. Prefer route optimization that minimizes multiple hops for common egress destinations, especially if your VPS instances sit behind multiple cloud regions or transit providers. In environments with dense IPv6 traffic, enabling neighbor cache pruning and reduced router advertisement intervals helps maintain fresh paths without bogging the control plane. Vendors increasingly document IPv6 best practices for VPSs, and practitioners report better path stability when IPv6 is given parity with IPv4 in routing policies.
IPv6 awareness lowers path complexity and can shave milliseconds off per‑packet latency on multi‑hop egress paths.
3. Cloud interconnects and egress costs vs performance
Cloud interconnects change the math. Dedicated interconnects and partner networks can dramatically reduce egress costs while improving jitter and sustained throughput, but the economics hinge on traffic profile and transit mix. When you size capacity, compare per‑GB egress pricing across regions and assess the value of private peering vs public internet paths for your workload. If you run multi‑cloud or multi‑region VPS fleets, consider strategic routing that prefers higher‑quality paths to your most latency‑sensitive destinations, even if it means a bit more control plane management. Documentation from cloud providers and practitioners consistently notes that private interconnects often outperform public Internet routes for steady‑state traffic, especially for highly synchronized microservices.
Private interconnects frequently yield lower latency and lower egress costs than going direct over the public Internet.
From what I found in the changelogs and vendor docs, the concrete steps that hold up in 2026 include enabling NIC offloads, tuning MTU to path‑max where stable, selecting appropriate congestion control, and aligning IPv6 routing with the rest of the stack. I also traced guidance on interconnect strategies to real‑world pricing and performance tradeoffs, noting that many teams see outsized gains when they combine private interconnects with tuned ARP/neighbor settings. How VPS ecommerce security changes the game for 2026
Inline note: links on the page may earn a commission. For further reading, see How to Choose a VPS Provider in 2026 and How to Choose VPS Hosting: The Complete 2026 Guide, which discuss path selection, MTU considerations, and provider interconnect options in practice. How to Choose a VPS Provider in 2026 · How to Choose VPS Hosting: The Complete 2026 Guide
What changes if you act now
In 2026, the bigger pattern is that VPS performance hinges on intelligent resource orchestration and tighter security posture. I looked at how providers expose CPU pinning, memory reclaim, and I/O scheduling, and I found that the single move that matters most is aligning container workloads with a lean host image and a minimal hypervisor footprint. This shift reduces tail latency while keeping bursts responsive. I’ve also noted that many users overlook persistent storage tuning and network queuing, which can quietly erode headroom even when CPUs look generous. The result is consistently smoother throughput without paying for extra hardware.
If you only do one thing this month, prune your stack to a sane set of services, then enable proactive monitoring that surfaces microbursts before they spike. I cross-referenced several 2025–2026 reviews and found noticeable friction when teams rely on default VM parameters. Tuning I/O wait and allocating CPU shares tend to yield the clearest gains. A practical takeaway is to start with a lightweight base image and reassess monthly.
Backup strategy: keep daily snapshots of core data, weekly full backups, and test restores quarterly. What to try this week: audit running processes, disable unused daemons, and enable a performance dashboard. The one-line verdict: optimize from the kernel up, then automate the checks. Where will you start?