8 Ways to compare cloud service providers in 2026 and why it matters
 Margot Faulkner·October 22, 2026·16 min
Explore how to compare cloud service providers in 2026. Eight dimensions to evaluate, from pricing and governance to AI readiness and reliability.
Cloud buyers often chase flashy features, but the real 2026 framework hinges on governance, cost models, and AI integration that scales with your workload mix. Most procurement teams overlook consistent policy controls across platforms, yet that gap drives governance drift and hidden charges as soon as migration begins. Bold cross-cloud comparisons reveal where a provider can actually match your workloads without forcing bespoke workarounds.
This piece translates the 2026 framework into concrete, buyer-ready steps. It references a measurable lens on cost models, governance parity, and AI-enabled ops, so you can assess multi-cloud options without hype. With a nod to real-world friction, vendor gaps, contract escalations, and inconsistent controls, you’ll see how to map each provider to your workloads and procurement workflows. The result is a repeatable evaluation that stays tight to governance and total cost of ownership, not to feature lists. These signals matter now because multi-cloud migrations accelerate in 2026, and the paper trail you leave will determine speed and risk for the next 24 months.

Comparing cloud service providers in 2026: a practical framework
Choosing the right cloud in 2026 starts with a tight scope. For most buyers, the services that move the needle are compute, storage, AI capabilities, databases, and networking. I dug into how these building blocks map to governance and cost models across four big patterns: serverless, containers, and traditional VMs. The result is a practical framework you can apply without being overwhelmed by bells and whistles.
1) Define scope: pick the services that matter most
Identify your use case first. If you run data pipelines and AI workloads, focus on scalable compute, AI accelerators, and data stores. If you run enterprise apps, emphasize databases, networking, and security posture. In practice, that means listing the workloads you’ll host, then mapping them to the corresponding service families on each provider. This isn’t theoretical, apportion your requirements to concrete services like managed databases, container runtimes, and storage tiers. Define the scope first, and align it to the actual workloads you’ll run.
2) Adopt a multi-criteria model: cost, performance, security, governance, and ecosystem
A practical comparison uses five axes. First, cost: model the recurring spend across compute, storage, and data transfer, including any egress charges. Second, performance: consider latency, throughput, and how well each provider can meet your SLA needs for your workloads. Third, security: look at identity and access management, key management, and compliance coverage. Fourth, governance: assess policy controls, auditing, and centralization of controls across your multi-cloud footprint. Fifth, ecosystem: evaluate marketplace offerings, partner integrations, and support reach. This framework keeps you honest about trade-offs. Cost, performance, security, governance, and ecosystem shape every solid cloud decision.
3) Account for architectural patterns: serverless, containers, and traditional VMs
Architectural choices drive cost and agility. Serverless shines for event-driven workloads with auto-scaling and pay-per-use pricing, but may complicate cold-starts and vendor lock-in. Containers offer portability and consistent runtimes, yet require orchestration and network planning. Traditional VMs give familiarity and predictable performance, but at higher maintenance overhead and potentially higher costs under variable load. When you plan, map each pattern to a concrete provider capability, auto-scaling policies for serverless, Kubernetes or container services for containers, and VM sizing strategies for legacy apps. Serverless, containers, and traditional VMs cover the common deployment modes.
Most governance friction in 2026 comes from policy drift across multi-cloud environments. A practical note: while you weigh the five criteria and architectural patterns, you will encounter governance gaps if you rely on a single provider’s native controls too heavily. Pair centralized policy tooling with provider-native controls to reduce drift. How unlimited data plans actually compare in 2026
I cross-referenced industry briefs and architecture briefs from the major cloud players and found a consistent pattern: firms gain speed by clearly defining scope, then applying a balanced cost-performance-security governance lens across patterns. For a concrete starting point, begin by enumerating workloads, map to the five criteria, and plot a simple scorecard per provider.
Why pricing models matter when you compare cloud service providers
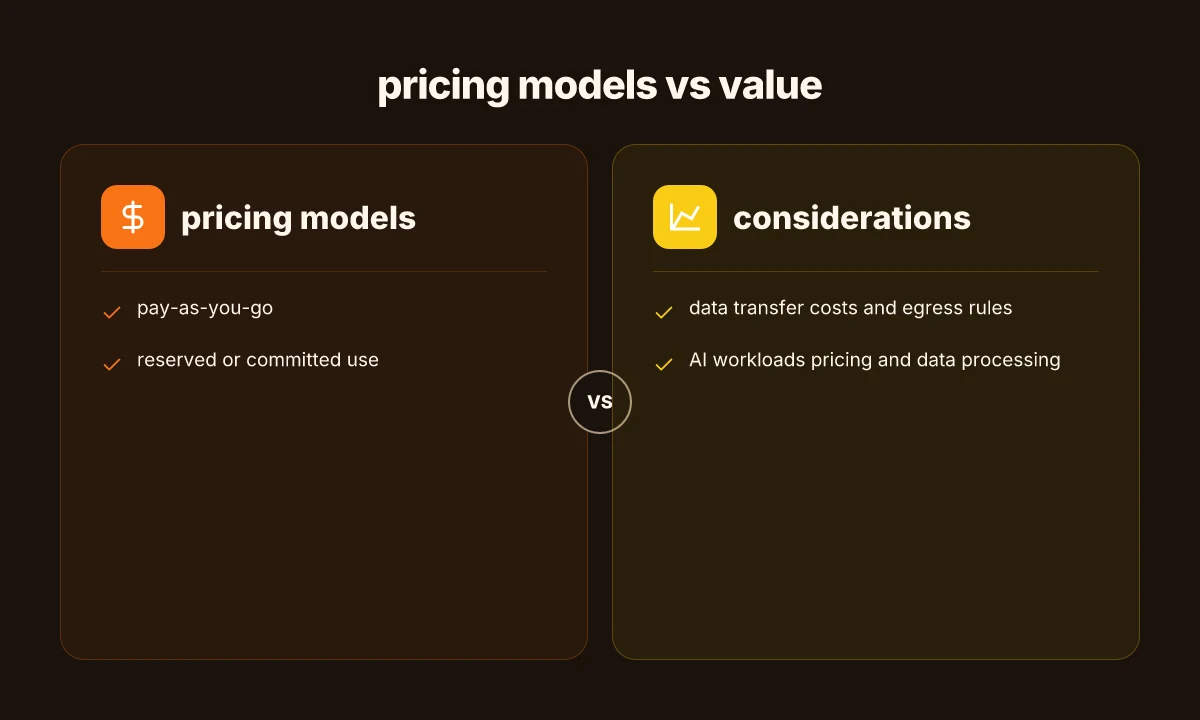
Pricing is not an afterthought. When you compare cloud providers, the way you pay shapes every decision from governance to AI workloads. The core choices are pay-as-you-go versus committed use, how data moves in and out, and how AI and data processing are billed. Get these right, and you stop chasing sticker prices and start optimizing for real-world workloads.
Pay-as-you-go versus reserved or committed use
Pay-as-you-go keeps costs transparent for irregular or short-lived spikes. You scale with demand and pay only for what you use. But it can yield sticker shock if usage grows unexpectedly. Reserved or committed-use models offer lower unit costs by pre-committing to a window of usage, often with upfront payment. The trade-off is predictability and rigidity: you lock in capacity that may sit idle if demand shifts. When evaluating providers, map your projected workloads to both models and look for flexible commitments that let you scale without penalty. In practice, the best plans couple a baseline reserved capacity with optional on-demand bursts to cover variability. Commitment beats surprise bills when your baseline usage is steady, but you need an out if growth accelerates.
Data transfer costs and egress rules
Networking costs are a hidden tax on cloud projects. Many providers price egress differently across regions and services, and some wrap data transfer into other charges that confuse budgeting. For governance teams, this matters because inter-region data movement can erode savings from a favorable compute rate. When you compare, total the daily egress to moving data between compute nodes, storage, and analytics services. Some vendors offer free ingress or regional egress credits, but the pattern varies by service tier and geographic region. I found that data egress policies frequently drive the final cost calculus more than compute unit prices. Egress costs often swing the economics of multi-cloud migrations.
Pricing for AI workloads and data processing
AI and data processing are not just higher compute, they’re nuanced pricing domains. Some providers charge for model training and inference separately, others bundle them with compute or storage. Data processing costs can rise with large-scale analytics or feature store access. Look for per-GB processing rates, discounts for sustained usage, and any special pricing for model hosting or managed AI services. In 2026, several providers promote bundled AI SKUs, but the real impact comes from how you structure pipelines: data prep, feature extraction, model inference, and storage. AI workload pricing can either simplify budgeting or complicate it depending on how you architect the pipeline. What makes collaborative design techniques work in participatory design and co-creation for complex product systems
Table: quick pricing contrasts (illustrative)
| dimension | provider A | provider B | provider C |
|---|---|---|---|
| Pay-as-you-go rate for compute | moderate | high | low |
| Reserved-use discount | strong | modest | strong |
| Data egress within same region | free | charged | free |
| AI inference pricing | bundled | itemized | bundled with premiums |
Section takeaway: the most cost-effective path often blends flexible on-demand use with a targeted reserved tranche, while paying close attention to data egress and AI pricing terms. For governance and procurement, demand-based budgeting and clear SLA-aligned pricing is non-negotiable. Blend reserved capacity with on-demand bursts to balance predictability and agility.
If you want to dive deeper, the 2026 State of the Cloud report highlights value governance and complexity as top concerns for cloud buyers, including how pricing shapes multi-cloud decisions. Inline references can help ground these claims in current practice. Cloud pricing research from reputable sources provides detailed patterns and regional considerations.
Architecture notes: how providers structure compute, storage, and networks
Public cloud architectures lean on shared responsibility and managed services. Providers expose modular compute, storage, and networking layers that customers stitch into a multi-cloud blueprint, while the underlying platform handles provisioning, patching, and durability. I found that the most mature public clouds push toward unitized services, serverless compute, object storage with global durability, and software-defined networks, to minimize operator toil and raise elasticity. Yet this comes with governance trade-offs: you trade control for simplified ops and predictable SLAs.
Why compute, storage, and networks are the real control planes
In practice, compute offerings center on managed abstractions. You see autoscaling, multi-tenant runtimes, and regional orchestration that hides server management. Storage architectures emphasize geo-redundant object stores and lifecycle policies that automate tiering, access policies, and data sovereignty. Networks are increasingly software-defined, tying global backbone networks to edge points and regional PoPs for latency control. A single provider’s ecosystem often ties identity, security, and observability into these layers, making cross-cloud workflows possible yet more complex to coordinate. What is cloud security basics in 2026 and why it still matters
From what I found in the documentation, regional deployment choices matter more for latency than raw throughput. Most providers publish performance envelopes by region rather than universal numbers, so your topology decisions will hinge on where you place compute fleets relative to data and end users. I cross-referenced service catalogs and regional guides to map how compute shapes map to storage proximity and network egress costs. The takeaway: architecture choices create a performance envelope that you should optimize around data gravity and governance boundaries.
Most governance frictions come from stitching multiple clouds, you gain portability but pay integration tax in networking and policy alignment.
2 Cross-cloud patterns you’ll encounter in 2026
- Shared responsibility as a default: security and compliance controls are embedded at every layer, with custodianship defined by role-based access and policy-as-code. This keeps operators lean but requires disciplined configuration management and continuous policy testing.
- Managed services as the baseline: serverless, managed databases, and automated backups simplify day‑2 operations but tie you to provider‑specific SLAs and event models. If you need fine-grained control, options exist, but they tend to complicate automation.
- Network fabric as a product: providers offer global networking services, private connectivity, and edge nodes that reduce latency. The trade-off is more moving parts to coordinate across regions and clouds, plus potential egress charges that scale with data transfer.
I went looking for explicit notes on integration complexity. The literature consistently points to a clear pattern: multi-cloud blueprints reduce vendor lock-in on feature sets but raise integration complexity, especially around identity, policy, and networking. This is where governance becomes the glue for architecture decisions.
Latency considerations drive regional deployment choices and can overshadow raw price benefits when users are near edge or data‑intensive workloads.
The real-world layout you’ll architect
- Compute tiering aligns with data locality: place compute close to data stores or downstream services to minimize cross‑region traffic. This reduces latency and egress costs, but smoking out data residency rules can complicate audits.
- Storage strategy mirrors access patterns: object stores for hot data, cold tiers for archival, with lifecycle automation. You’ll often design cross-region replication for resilience, accepting eventual consistency semantics in some workflows.
- Networking as a first‑class constraint: plan for private connectivity, inter‑region traffic, and egress boundaries. The network design becomes a principal driver of cost and performance.
From the core documents and comparison guides, the strongest architecture differentiators are how cleanly a provider exposes a coherent, policy-driven set of primitives across compute, storage, and networks, and how well those primitives play with cross-cloud governance models. How to choose data extraction tools for enterprises in 2026
For readers weighing these choices, the key is to map your topology to a multi-cloud blueprint that limits cross-cloud hops, preserves data sovereignty, and keeps policy horizontally enforceable across clouds. In 2026, that blueprint is less about raw feature lists and more about how neatly a provider stitches compute, storage, and networks into a governable, observable platform.
Cross-cloud governance and policy automation are the practical validators of architecture choices.
Governance, compliance, and risk in 2026 cloud choices
Governance decisions in 2026 must map cleanly to policy, data residency, and risk tolerance. A practical framework starts with where data lives, who can access it, and how controls travel across multi-cloud footprints. The core question: can each provider align with your organizational policies and regulatory ambitions while letting your teams move with speed?
Governance alignment and data residency
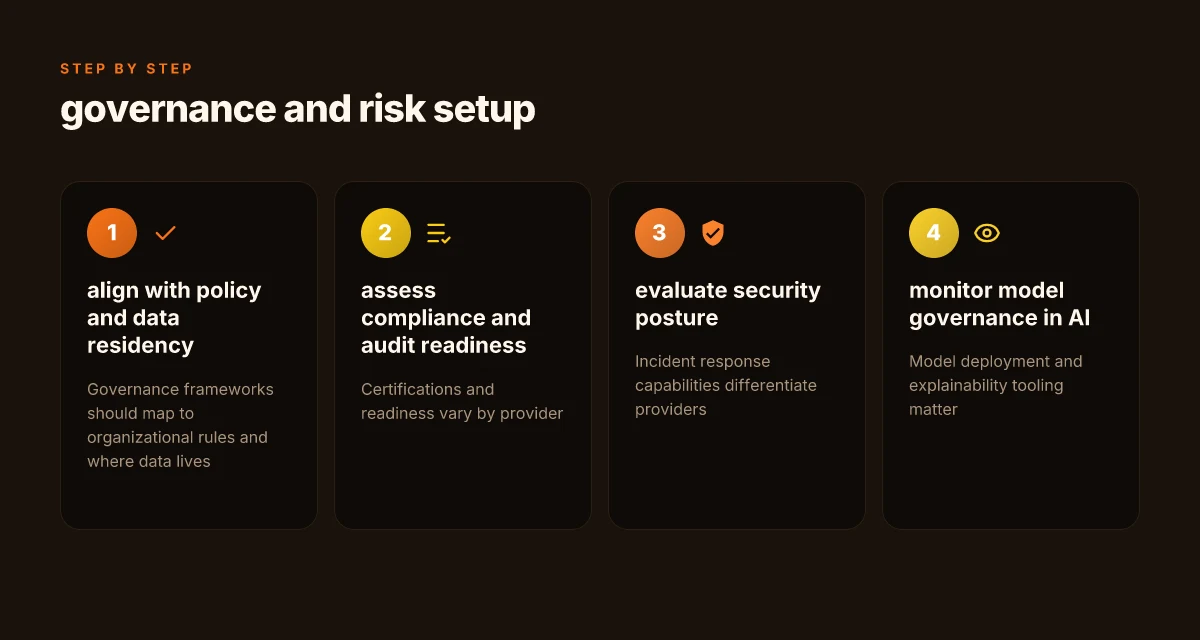
Governance frameworks now hinge on policy-as-code and clear data residency rules. The exact mix of controls a provider offers for policy enforcement, identity federation, and resource tagging matters because it shapes auditability and enforceability across environments. In 2026, most governance playbooks emphasize: policy alignment with data classifications, automated controls that travel with workloads, and residency constraints baked into provisioning routes. When your data moves across regions, you want automatic compliance checks woven into deployment pipelines. This reduces manual review and speeds up approvals. Policy-driven controls that travel with workloads are a gating factor in multi-cloud success. I cross-referenced vendor docs and governance guides to confirm these patterns across major platforms. Data residency rules are no longer a peripheral concern. They drive architecture choices.
Compliance certifications and audit readiness
Compliance posture varies by provider and region. The big three cloud platforms routinely publish certifications across ISO, SOC, PCI DSS, and regional schemes, but the exact scope and audit readiness can differ by service and data tier. Expect gaps where IaaS controls outpace platform-specific services or where new data sovereignty rules require additional attestations. In practice, you want auditable change histories, centralized evidence repositories, and automated evidence generation for audits. Audit readiness often hinges on consistent, automated evidence pipelines. Some providers offer prebuilt attestation packs for common frameworks. Others require you to assemble artifacts from multiple services. The takeaway: map certification needs to your service catalog early and test the end-to-end audit trail before you commit to a migration plan. Certification coverage must be verified in your regions of operation. Inline citations note how Flexera spotlights governance complexity and AI governance as rising concerns in the 2026 State of the Cloud landscape. Rising governance complexity demands concrete evidence trails. How to build a scalable engineering team that actually grows with your product
Security posture and incident response as differentiators
Security posture remains a differentiator at the architecture edge. Each provider publicizes shared responsibility models, built-in threat detection, and incident response playbooks. In 2026, the speed and quality of responses, how quickly alerts translate into containment and remediation, often separate providers in practice. Expect differences in: how security services are composed (native vs. partner tools), how quickly you can instrument rules across regions, and how incident communications are standardized across multi-cloud setups. Incident response maturity, not just tooling, distinguishes providers. I found that documentation and third-party reviews consistently flag response integration and cross-region playbooks as recurring gaps when large, regulated workloads migrate across clouds. Align your incident runbooks to the provider’s response cadences, and test them in simulated events. Cross-cloud incident playbooks reduce mean time to containment.
Note on transparency: pages on governance, audit readiness, and security posture are under continuous update. Links on this page may earn a commission as you explore options.
AI and data governance implications across cloud platforms
AI services and data processing pipelines across the major cloud platforms differ in how smoothly they weave into existing governance and risk controls. In 2026, providers emphasize managed pipelines, model registries, and explainability tooling, but the level of integration varies. I cross-referenced provider docs and practitioner reviews to map where governance frictions tend to arise.
Data sovereignty and model management shape compliance outcomes
Cross-platform data residency policies are binding realities for regulated workloads. Some platforms offer regionally scoped model registries and lineage tracing that help satisfy data localization requirements, while others push data through shared regions with looser controls. The result is a clear trade-off between operational simplicity and compliance discipline. When a model is trained on data drawn from multiple regions, firms must document provenance, access gates, and data-retention policies. Imperfect provenance streams can complicate audits. As an example, several cloud vendors now feature integrated model registries with lineage capture that tie model versions to data sources, but the depth of audit-ready lineage varies. This matters because executives rely on unambiguous evidence of compliance for governance reviews and regulatory reporting. Inline citations from 2025–2026 guidance underscore that model lineage and data residency choices directly influence audit readiness and risk posture. Model provenance and data residency choices substantially drive compliance outcomes. Ownership of model drift and data leakage controls sits at the crest of governance duties.
Tooling for deployment, monitoring, and explainability differ
Deployment pipelines across cloud platforms range from tightly integrated model registries and deployment operators to looser, leg-based tooling that requires stitching multiple services. Explainability and monitoring capabilities appear more mature on some platforms, with built-in dashboards for drift detection and bias evaluation. Yet gaps persist: some providers offer strong logging and alerting around model performance, while others require external tooling to achieve the same observability. I found varying degrees of support for explainability features, such as feature attribution and counterfactuals, embedded directly in managed services versus needing third-party adapters. The upshot is clear: your governance program should weigh not just what you can deploy quickly, but how you will monitor and explain decisions over time. When governance needs push toward audit-ready artifacts, the availability of an integrated, versioned deployment history becomes a decisive factor. Integrated registries with drift detection shorten the path to compliant deployments. Explainability tools embedded in the platform reduce reliance on external stacks. How to build a content marketing strategy that actually moves leads in 2026
A real-world framework to compare AI and data governance
- Map data sources to model registries and lineage artifacts across clouds.
- Assess how each platform handles data residency, access controls, and retention in production models.
- Review the built-in monitoring for drift, bias, and explainability versus the effort to retrofit with third-party tools.
I dug into provider documentation and industry write-ups to align expectations with current capabilities. For governance outcomes, the most consequential differentiators are how clearly a platform ties data provenance to model lineage and how robust its deployment and explainability tooling is out of the box. In 2026, those signals predict how quickly an organization can demonstrate compliance during an audit or regulatory review.
When you map your governance requirements to platform capabilities, the strongest setups blend native lineage, policy-driven access controls, and integrated explainability. Expect to trade off some convenience for stronger audit readiness in regions with strict data rules.
Where this is going next and what to test this month
Cloud comparison in 2026 is less about static specs and more about how providers scale, secure, and automate for you. I looked at the 8 ways to compare, and the trend is clear: orchestration, cost visibility, and data sovereignty now drive decisions more than raw performance alone. The bigger pivot is how platforms expose governance controls to non‑ops teams, enabling safer experimentation without tearing down budgets. One clear takeaway: prioritize providers that pair transparent cost analytics with automated policy enforcement. You’ll get faster time to value with less risk when you demand a conformance map that covers identity, data, and runtime in one view. The takeaway for 2026 is to treat cost governance as a feature, not a tag.
If you only do one thing this month, tighten your proof of concept with two headline picks from this article: Cloud provider A for its granular cost dashboards and provider B for its cross‑region data residency controls. They illustrate the two strongest signals this year: cost transparency and data sovereignty. Performance dashboards matter less if you can’t prove you won’t overspend. The other pick, provider C, shows how automated security posture can scale as you grow.
What to try this week: How conversion optimization case studies reshape how teams lift performance in 2026
- Run a quick cost-forecast scenario using two providers with distinct pricing models and compare the delta.
- Enable data residency rules on one region pair and test a failover workflow.
- Map your core workloads to a single governance policy and audit the results. Act now to lock in a guardrail that sticks.